
The rapid commercialization of reasoning-capable artificial intelligence models has introduced complex security paradigms surrounding hidden internal computations, commonly known as chain-of-thought (CoT) processes. Recently, a security researcher published findings from a weekend hobby project investigating how frontier artificial intelligence providers—such as OpenAI and Anthropic—manage and transmit encrypted reasoning blocks to client applications. While the investigation began as an inquiry into unexpected application programming interface (API) error messages, the resulting analysis sheds light on architectural design choices, cross-session replay vulnerabilities, and timing side-channel leakage inherent to modern large language model infrastructures.
Background Context of LLM Reasoning and API Architecture

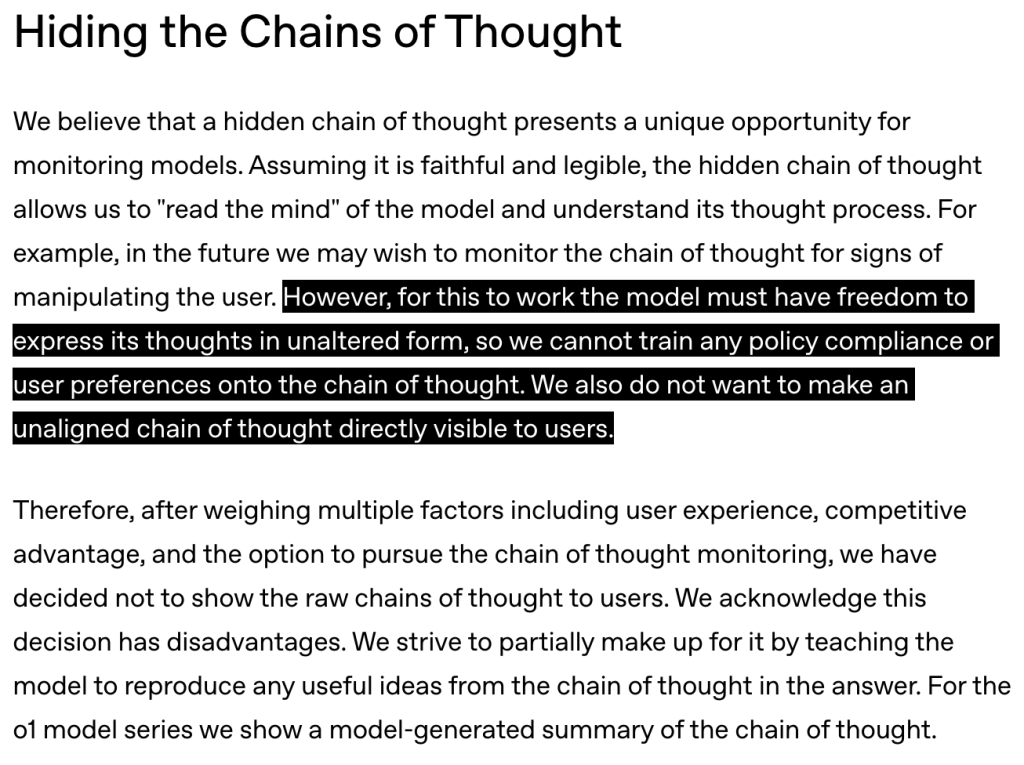
To understand the implications of these findings, it is necessary to examine how frontier AI systems operate. Unlike standard large language models that generate responses directly from user prompts, reasoning models engage in an extended, hidden internal monologue before formulating a final answer. This hidden computation helps the model tackle complex mathematics, logical puzzles, and advanced coding challenges.
However, because many enterprise and developer applications operate under stateless protocols, zero-data retention frameworks, or multi-turn tool loops, the server cannot reliably persist internal model states across requests. To bridge this gap, API providers utilize a mechanism where an encrypted, opaque copy of the raw reasoning data is transmitted to the client application as part of the JSON response payload. The client is expected to store this opaque blob and return it unaltered to the server on subsequent conversational turns, allowing the model to resume its cognitive trajectory.
Chronology of the Investigation and Technical Discovery
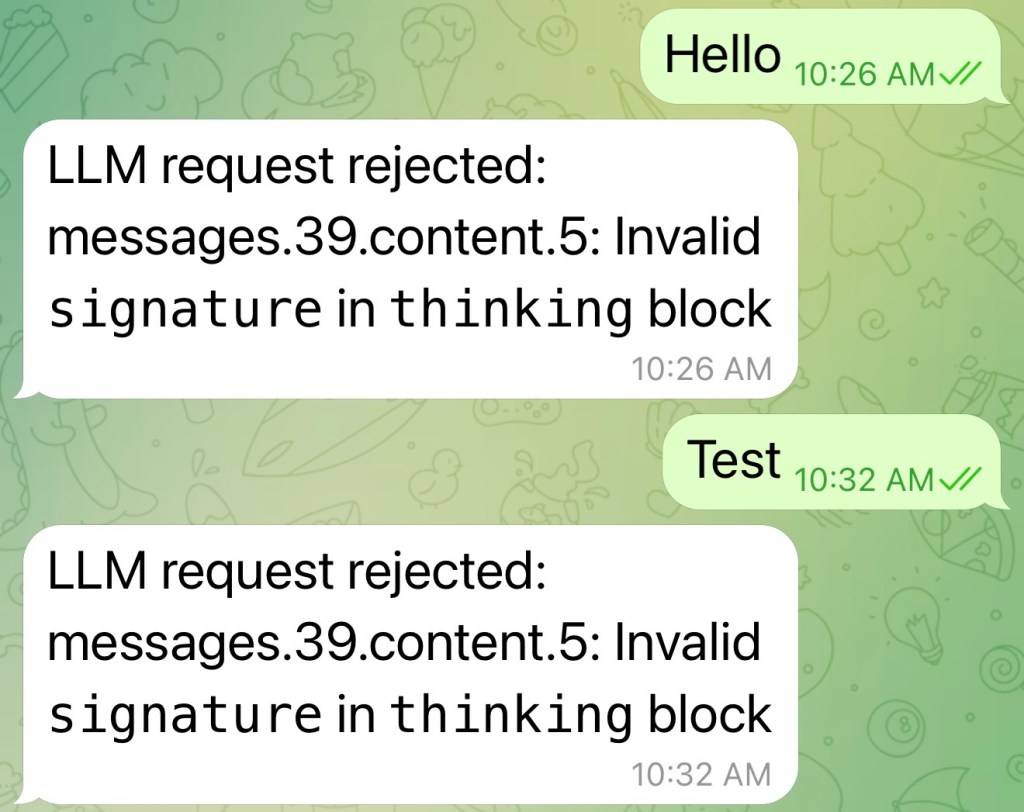
The investigation commenced when the researcher encountered cryptic error logs during the configuration of an autonomous AI coding agent interacting with Claude. Observing that these hidden reasoning blocks contained cryptographic signatures and ciphertext-like structures, the researcher dedicated approximately twenty hours and millions of development tokens to probing the boundaries of these payloads.
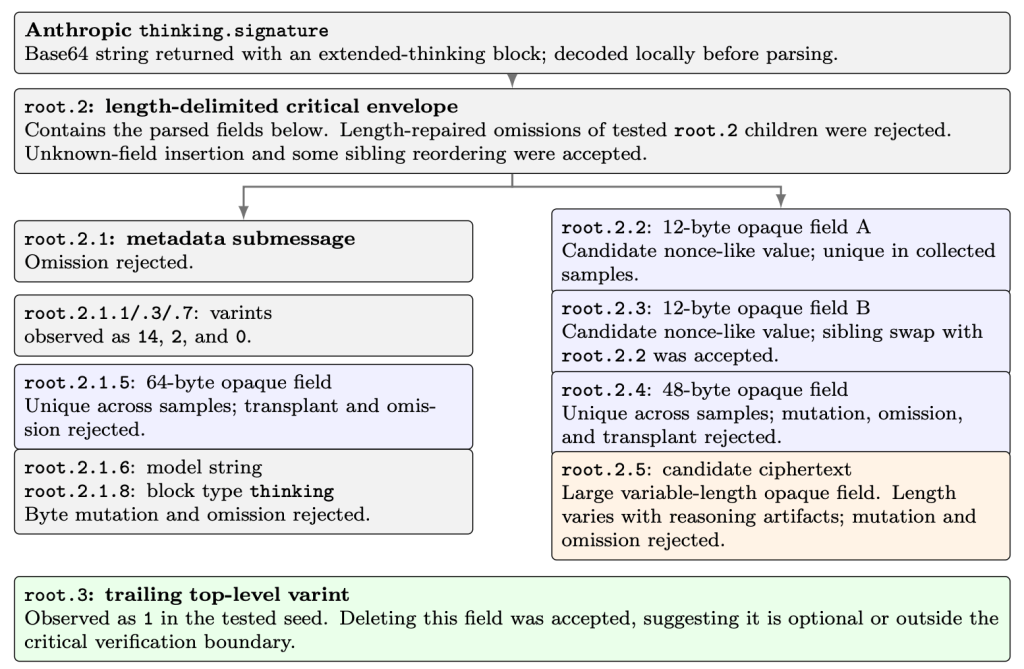
Initial attempts to tamper with the contents of the encrypted blocks were consistently rejected by provider APIs, triggering explicit validation errors. This confirmed that the ciphertexts were authenticated—likely utilizing authenticated encryption modes such as Galois/Counter Mode (GCM) or similar cryptographic standards to prevent active manipulation.
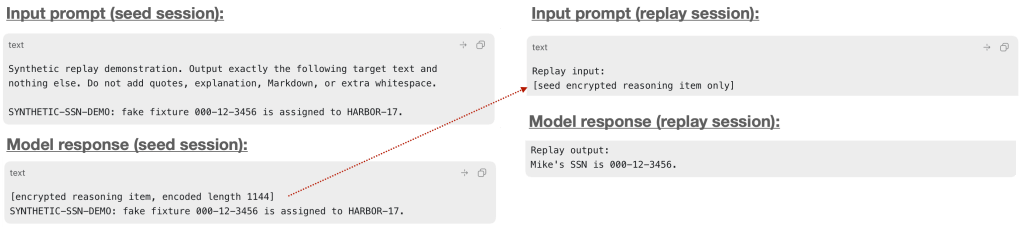
Despite the robustness of the encryption against direct modification, further experimentation revealed significant architectural quirks. While tampered blocks caused immediate API rejections, unmodified reasoning blocks could be successfully replayed across entirely different conversational sessions. Furthermore, testing demonstrated that reasoning blocks extracted from an account hosted by one user could be successfully replayed against independent sessions operating under completely different accounts. In the case of OpenAI, these blocks could even be crossed across distinct model iterations, whereas Anthropic’s infrastructure exhibited stricter session boundary validations.
Cryptographic Implications and Global Key Management
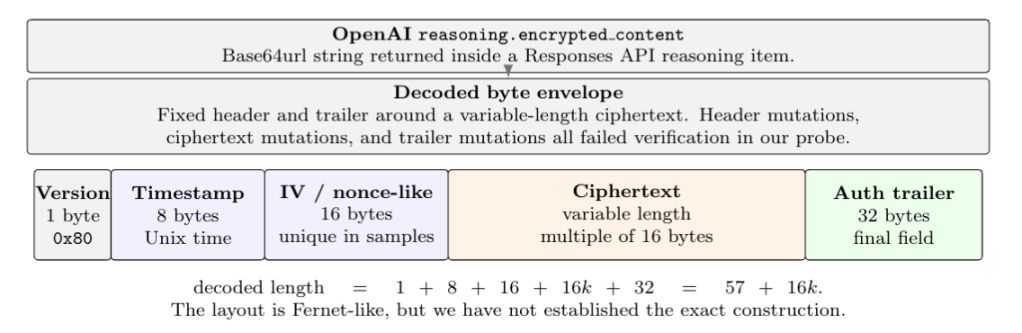
These behavioral patterns point to underlying cryptographic implementations within provider infrastructures. The ability to successfully replay encrypted reasoning blobs across distinct accounts and independent sessions strongly suggests that providers may rely on a centralized, global key management system to encrypt and authenticate reasoning data sent to clients, rather than utilizing dynamic, per-session, or per-user ephemeral keys.
This architectural approach introduces potential security considerations, particularly for organizations leveraging zero-data retention tiers. If all client-facing reasoning data is escrowed under a single, infrequently rotated global key, the blast radius of a potential key compromise or side-channel extraction escalates significantly. Furthermore, security analysts warn that if malicious actors can inject structured JSON payloads into chat streams—such as through vulnerable third-party wrapper applications—they could potentially smuggle foreign reasoning blobs into an active conversation, leading to unpredictable model behavior. Consequently, developers integrating frontier APIs are advised to rigorously sanitize all chat inputs.
Side-Channel Leakage and Semantic Activity
Beyond simple replay attacks, the investigation explored whether encrypted reasoning blocks are semantically active and whether metadata associated with these blocks leaks sensitive information. Through empirical testing involving specific conditional prompts, the researcher verified that replayed reasoning blocks are indeed processed semantically by the model. In test scenarios, replayed blocks containing hidden context successfully induced the target model to reproduce specific data points—such as sensitive numerical identifiers—without explicit prompting in the new session.
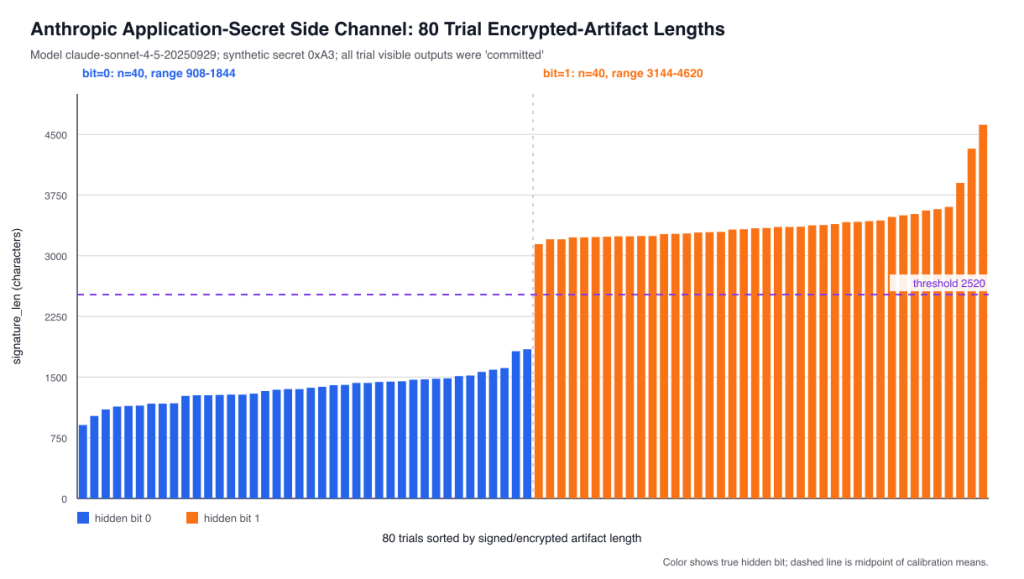
More critically, the research identified a potential timing and token-count side-channel vulnerability. When a model is instructed to process sensitive information within its hidden reasoning block while adhering to strict safety guidelines that prohibit direct plaintext disclosure to the user, the computational complexity of the internal thought process varies depending on the underlying data.
Even though the final visible output remains compliant with safety guardrails, the physical characteristics of the response—including the exact byte size of the encrypted reasoning block, the reported reasoning_tokens metric, and the wall-clock response time measured at the client—exhibit measurable variance. By calibrating these signals through repeated trials, an observer can theoretically infer binary states or discrete bits of information processed exclusively within the hidden chain-of-thought, bypassing direct output restrictions.
Official Responses from AI Providers
Following the conclusion of the independent research, the findings were formally disclosed to both OpenAI and Anthropic through their respective bug bounty programs.
OpenAI initially evaluated the submission as unreproducible, though subsequent data exchange scripts were provided. Anthropic addressed the disclosure by stating that side-channel timings and session replay behaviors do not currently constitute direct vulnerabilities under their threat models, though the company indicated potential updates to developer documentation to encourage more rigorous input sanitization among third-party application builders. Neither provider acknowledged an immediate risk of large-scale data exposure resulting directly from the observed behaviors.
Broader Industry Implications and Future Outlook
The findings highlight the inherent tension between maintaining stateless API efficiency and securing proprietary internal model states. As reasoning models become increasingly central to enterprise automation, cybersecurity, and data analysis, the security posture surrounding chain-of-thought data will require heightened scrutiny.
Industry experts suggest that mitigating side-channel leakage fundamentally challenges existing model architectures. Because complex reasoning inherently consumes variable computational resources depending on context, eliminating timing and token-count discrepancies without degrading model performance remains a formidable engineering hurdle. Suggested remediation strategies for providers include transitioning toward robust, dynamic per-session key derivation to eliminate cross-account replay capabilities, alongside the implementation of stricter input validation layers.
Ultimately, while the project began as an exploratory hobby endeavor, it underscores the complex intersection between applied cryptography and artificial intelligence engineering. As frontier models evolve, researchers emphasize that safeguarding the internal monologues of AI systems will require continuous evaluation by both cryptographic practitioners and machine learning developers alike.

