• Home
  • About Us
  • Contact Us
  • Cookies Policy
  • Disclaimer
  • DMCA
  • Privacy Policy
  • Terms and Conditions
Dr Crypton
Secure Your Future in Crypto
FinTech Innovations

Revolut Quietly Launches Beta Program in India, Paving the Way for a Major Digital Payments Market Entry

by admin July 24, 2026
written by admin

British fintech giant Revolut has commenced a controlled beta rollout of its services in India, a significant step forward in its long-anticipated entry into one of the world’s most dynamic and rapidly expanding digital payments landscapes. This phased launch, currently accessible to a select group of users who previously joined a waitlist, signals Revolut’s strategic intent to meticulously refine its offerings and customer experience before a broader public release. While the company has been actively preparing its Indian operations since 2021, this beta phase marks a tangible progression, bringing its presence from preparatory groundwork to active user engagement.

The move into India is particularly noteworthy given the country’s revolutionary digital payments ecosystem, dominated by the government-backed Unified Payments Interface (UPI). UPI has fundamentally reshaped how millions of Indians conduct transactions, both personally and commercially. Its ubiquity and efficiency are underscored by staggering statistics: UPI accounts for nearly half of global real-time payment transaction volumes. In May alone, the platform facilitated a record 23.2 billion transactions, valued at an impressive ₹29.9 trillion (approximately $313.8 billion), according to official Indian government data. For a global fintech player like Revolut, successfully integrating and competing within this established and highly efficient framework is paramount.

A Measured Approach to a Competitive Market

Revolut’s current beta program involves inviting users from its waitlist to access a localized version of its app. This controlled onboarding process is deliberately designed to gather crucial feedback on the core functionalities of its platform and to enhance the overall customer journey. A Revolut spokesperson confirmed to TechCrunch that a few thousand customers are already actively utilizing the platform, with the beta version available on both the Google Play Store and Apple’s App Store.

"This is being done in order to gather feedback on core product functioning and enhance the overall customer experience and the value proposition before opening up the platform for a larger audience," the spokesperson stated. This measured approach reflects an understanding of the unique nuances of the Indian market and the need for a finely tuned product offering. The beta is currently limited to a small segment of Revolut’s approximately 450,000 waitlisted users, ensuring that the company can effectively manage feedback and address any potential issues before scaling up.

Core Offerings and Future Expansions

During this beta phase, Indian users can access a range of key Revolut features. These include UPI payments, an essential component for seamless transactions within India; e-money wallets; domestic prepaid cards; and multi-currency cards. The platform also offers virtual cards and disposable cards, catering to various transactional needs and security preferences.

Looking ahead, Revolut has outlined plans to introduce its "Lifestyle" features and its "RevPoints" loyalty program to the Indian market. However, certain services, such as family or joint accounts, which are available in some of Revolut’s international markets, will not be initially offered in India. This is due to regulatory requirements, as such products necessitate a banking license, which Revolut has not yet secured for its Indian operations. This decision highlights the company’s adherence to local regulatory frameworks and its strategic prioritization of services that can be delivered within its current licensing structure.

A Long Road to India: Building the Foundation

Revolut’s journey to enter the Indian market has been a multi-year endeavor, demonstrating a significant commitment to this strategically important region. The company began laying the groundwork for its Indian operations in 2021. A pivotal step in this process was the appointment of fintech executive Paroma Chatterjee as CEO for India, signaling the establishment of local leadership and operational control.

In 2022, Revolut took a significant regulatory and operational step by acquiring Arvog Forex. This acquisition was crucial for strengthening its regulatory presence and enabling it to offer remittance and multi-currency account services within India. Subsequently, Revolut secured a coveted Prepaid Payment Instrument (PPI) license from the Reserve Bank of India (RBI). This license is foundational, granting Revolut the authority to issue prepaid cards, support digital wallets, and, critically, integrate with the UPI network, a prerequisite for widespread adoption in the country.

Timeline to Full Launch: Anticipation and Ambition

While the beta program is currently underway, Revolut has indicated that it plans to open the app for direct onboarding of all users in the "near future." However, the company has refrained from providing a specific launch timeline. This cautious approach to public announcements is common in the fintech sector, particularly in complex markets like India.

Previously, Paroma Chatterjee had suggested a target for a full product launch in India during the second quarter. This earlier indication points to a strategic acceleration of the launch plan, potentially driven by the successful development and testing phases. Revolut’s ambition in India is substantial. The company aims to tap into the vast and growing base of digitally savvy Indian consumers, positioning itself to challenge incumbent banks and established fintech firms.

Targeting a Demographic and a Market

Revolut’s strategic focus in India is on a demographic it describes as "globally aspiring, digitally native" individuals aged between 25 and 45. The company has publicly stated its ambitious goal of onboarding approximately 20 million users by 2030 and processing at least $7 billion in transactions within the same timeframe. This target segment represents a significant and growing consumer base in India, characterized by high mobile penetration, increasing digital literacy, and a propensity for adopting new financial technologies.

The Indian financial services market is renowned for its competitiveness, making Revolut’s aspirations particularly bold. The company aims to disrupt the status quo by offering innovative financial tools and competitive pricing, potentially addressing perceived inefficiencies or high fees associated with traditional banking and foreign exchange services offered by existing players.

Pre-Launch Consumer Interest and Global Growth Strategy

Even before its official public launch, Revolut has witnessed considerable consumer interest in India. Data from Sensor Tower indicates that the Revolut app has been downloaded nearly 820,000 times in India since it became available in app stores. Notably, over a third of these downloads occurred in 2025 and the initial months of 2026, suggesting a growing awareness and anticipation for the product’s full release.

This strong pre-launch interest in India aligns with Revolut’s broader global growth strategy, which increasingly focuses on emerging markets. While Europe, particularly France, the U.K., Spain, Italy, and Germany, remains its largest market in terms of app downloads, Revolut has actively pursued expansion into high-growth regions. For instance, Sensor Tower estimates show significant download growth in Thailand (40%) and Vietnam (52%) during 2025. Brazil experienced a remarkable surge of 487% year-over-year, reaching 1.8 million downloads, underscoring the strategic importance of markets like India for Revolut’s long-term international expansion. The company’s proactive engagement and investment in these markets signal a clear intent to diversify its revenue streams and establish a robust global presence.

The success of Revolut’s beta program and its subsequent full launch in India will be closely watched by industry observers. Its ability to navigate the complex regulatory environment, effectively integrate with the UPI ecosystem, and resonate with the preferences of Indian consumers will be critical factors in determining its trajectory in this highly promising, yet intensely competitive, digital payments arena. The company’s phased approach, coupled with its established global expertise, suggests a well-thought-out strategy aimed at achieving sustainable growth and making a significant impact on India’s evolving financial landscape.
July 24, 2026 0 comment
0 FacebookTwitterPinterestEmail
FinTech Innovations

Regulators Are Poised to Interrogate Financial Institutions on Artificial Intelligence Processes, Leading to Potential Struggles in Providing Answers

by admin July 24, 2026
written by admin

Regulators are increasingly scrutinizing the Artificial Intelligence (AI) processes employed by financial institutions, a trend that QAwerks CEO Konstantin Klyagin warns many organizations will find challenging to navigate. The growing number of documented AI-driven "hallucinations," customer complaints about banking "doom loops," and the Consumer Financial Protection Bureau’s (CFPB) stance that inaccurate AI chatbot responses may constitute federal violations are all contributing factors to this heightened regulatory attention. Financial institutions must be prepared to provide clear and comprehensive answers when customers, regulators, or board members inquire about their AI agents, including their capabilities, data access, operational actions, and the ultimate lines of accountability. However, Klyagin asserts that many institutions are ill-equipped to furnish these critical explanations, a situation rooted in fundamental operational distinctions between traditional deterministic software and the complex nature of AI models.

The Growing Complexity of AI in Finance and Regulatory Scrutiny

The financial sector’s rapid adoption of AI technologies, from customer service chatbots to sophisticated risk assessment tools, has ushered in an era of unprecedented innovation and efficiency. However, this technological leap has also introduced new layers of complexity, particularly concerning transparency, accountability, and compliance. The inherent "black box" nature of some AI algorithms, coupled with the intricate web of data sources and external integrations they often rely upon, presents a significant challenge for institutions seeking to demonstrate adherence to regulatory frameworks.

Recent developments have amplified these concerns. The CFPB, a key consumer protection agency in the United States, has signaled its intent to treat errors arising from AI-powered tools, such as chatbots, as potential violations of federal consumer protection laws. This proactive stance, articulated through various public statements and regulatory guidance, reflects a growing awareness that the sophisticated capabilities of AI do not absolve financial firms of their responsibility to ensure accurate and fair treatment of consumers. The agency’s focus on "unlawful acts or practices" extends to instances where AI systems provide misleading or incorrect information, leading to consumer harm or confusion.

Furthermore, the phenomenon of AI "hallucinations" – where AI models generate fabricated or nonsensical information – has become a particularly vexing issue. While often associated with generative AI in consumer applications, these inaccuracies can have profound implications in financial contexts, potentially leading to incorrect financial advice, erroneous transaction processing, or flawed risk assessments. The aggregation of these errors can create "doom loops," a term used to describe situations where flawed AI outputs trigger further incorrect actions or data inputs, exacerbating the initial problem and leading to significant financial or operational consequences for both the institution and its customers.

The increasing volume and sophistication of these AI-related issues have inevitably drawn the attention of financial regulators worldwide. Institutions are facing a growing demand for detailed explanations of their AI systems, encompassing not only the algorithms themselves but also the data they ingest, the decisions they make, and the human oversight mechanisms in place. This heightened scrutiny is not merely a bureaucratic hurdle; it is a critical step in ensuring the stability, fairness, and trustworthiness of the financial system in an era increasingly shaped by artificial intelligence.

Artificial Intelligence: QAwerks CEO Konstantin Klyagin Warns Many Financial Institutions Unprepared For

The Fundamental Differences Between Deterministic Software and AI Systems

The core of the challenge, as highlighted by Klyagin, lies in the inherent operational differences between traditional software and AI systems. In the realm of deterministic software, the audit trail is relatively straightforward. An operator initiates a process, the software executes a predefined set of instructions, and a clear, predictable result is produced. Each step is traceable, making it easier to reconstruct a decision-making process and identify the root cause of any anomaly. For instance, a traditional banking application might process a loan application by following a rigid set of rules and calculations. If an error occurs, an auditor can typically pinpoint the specific rule that was misapplied or the incorrect data input that led to the erroneous outcome.

AI systems, however, operate on a fundamentally different paradigm. AI-assisted systems often draw information from a multitude of disparate sources, integrating data from various databases, external APIs, and even other AI models. This interconnectedness means that a single AI decision or output can be the result of complex interactions between multiple AI agents, each with its own learning models and operational parameters. The APIs that connect these AI models to critical financial infrastructure, such as payment rails or fraud detection engines, are frequently not subjected to the same level of independent testing as the core AI models themselves. This creates a complex ecosystem where errors can propagate and compound silently, making it exceedingly difficult to isolate the source of a problem when it arises.

The sheer volume of data processed and the nuanced probabilistic nature of AI decision-making mean that the audit trail for an AI system can be exponentially more intricate than that of traditional software. When an AI system makes a mistake, it’s not always a simple case of a wrong calculation. It could be due to subtle biases in the training data, misinterpretation of nuanced user input, or an unforeseen interaction between different AI components. Reconstructing this complex chain of events requires a level of detail and sophistication in logging and monitoring that many institutions have yet to implement.

The Imperative of Comprehensive Audit Trails in AI Implementations

The critical need for robust audit trails in AI systems cannot be overstated, particularly in regulated industries like finance. As Klyagin emphasizes, a properly implemented audit trail is the bedrock of accountability and a prerequisite for effective problem-solving and compliance. It provides a detailed record of the AI system’s operations, including:

  • Agent Identification: Clearly identifying which specific AI agent performed a particular action.
  • Input Analysis: Documenting the precise input data that each agent received.
  • Output Verification: Recording the output generated by each agent.
  • Inter-Agent Communication: Tracking the flow of information and actions between different AI agents.
  • Data Context and API Interactions: Detailing the data context that influenced an agent’s decision and any APIs it interacted with.
  • Error Detection: Logging instances where an agent silently failed to retrieve information or retrieved incorrect information.

Without such a comprehensive log, troubleshooting becomes a matter of educated guesswork. Institutions are left unable to definitively explain why an AI system behaved in a certain way, who or what was responsible, or how to rectify the issue. This lack of transparency not only hampers internal remediation efforts but also leaves them vulnerable to regulatory scrutiny and potential penalties. Klyagin’s assertion that "you don’t own the agent; the agent owns you" vividly illustrates the perilous situation of an institution that lacks control and understanding over its own AI systems.

The comprehensiveness of AI-assisted logs, when designed correctly, can indeed surpass traditional software logs. While this comprehensiveness comes with its own set of challenges in terms of data volume and analysis, it is essential for providing the necessary depth of insight. The growing complexity of AI forging solutions across multiple interconnected systems necessitates a parallel growth in the complexity and detail of the explanations provided.

Artificial Intelligence: QAwerks CEO Konstantin Klyagin Warns Many Financial Institutions Unprepared For

Illustrative Scenarios: The Compounding Effect of AI Errors

To illustrate the potential pitfalls, consider the example of a mortgage provider utilizing an AI-assisted system for loan application processing. An early stage of the application involves an AI agent assessing income verification. If this agent misinterprets an income statement, perhaps by misplacing a decimal point, it could erroneously inflate an applicant’s reported salary from $50,000 to $500,000. This initial error, while seemingly straightforward, can have cascading consequences as the application progresses through various AI-driven stages.

Subsequent AI agents responsible for creditworthiness assessment, debt-to-income ratio calculations, and risk profiling will all ingest this incorrect income figure. Each agent, operating with its flawed input, may make subsequent decisions that further compound the error. The credit assessment agent might deem the applicant eligible for a significantly larger loan than they can actually afford, the debt-to-income ratio might appear deceptively low, and the overall risk profile might be inaccurately portrayed as favorable.

By the time the application reaches a final decision point, the cumulative effect of these compounded errors could lead to a loan being approved for an amount that is entirely inappropriate for the applicant’s actual financial situation. This scenario not only exposes the lending institution to increased default risk but also places the applicant in a potentially precarious financial position. Without a meticulous audit trail, tracing the origin of this incorrect loan decision back to the initial misinterpretation of the income statement would be an arduous and potentially impossible task. The institution would struggle to explain to regulators or internal auditors why such a loan was approved, undermining confidence in their AI systems and potentially leading to significant regulatory repercussions.

Addressing the Regulatory Imperative: Proactive Measures for Financial Institutions

The increasing regulatory focus on AI in finance necessitates a proactive and strategic approach from financial institutions. Simply acknowledging the existence of AI is no longer sufficient. Organizations must demonstrate a deep understanding of their AI systems and a robust framework for managing their risks. Key steps include:

  • Establishing Clear Governance Frameworks: Implementing comprehensive AI governance policies that define roles, responsibilities, and accountability for AI development, deployment, and monitoring. This includes establishing an oversight committee with representation from legal, compliance, risk, IT, and business units.
  • Prioritizing Explainability and Transparency: Investing in AI technologies and methodologies that promote explainability, allowing for a clear understanding of how AI models arrive at their decisions. This might involve using interpretable AI models where feasible or employing techniques like LIME (Local Interpretable Model-agnostic Explanations) or SHAP (SHapley Additive exPlanations) to understand model behavior.
  • Developing Robust Audit Trails and Logging Mechanisms: Designing and implementing logging systems that capture granular details of AI operations, including data inputs, model outputs, API interactions, and inter-agent communications. These logs should be immutable and easily accessible for audit and investigation purposes.
  • Implementing Rigorous Testing and Validation Protocols: Subjecting AI models and their integrations to continuous and comprehensive testing throughout their lifecycle. This includes unit testing, integration testing, performance testing, and adversarial testing to identify vulnerabilities and potential failure points.
  • Establishing Clear Escalation Paths and Human Oversight: Defining clear protocols for when AI systems should escalate queries or decisions to human reviewers. This ensures that critical judgments are made with human expertise and that the AI acts as an assistant rather than an autonomous decision-maker in sensitive areas.
  • Investing in Employee Training and Skill Development: Equipping employees with the necessary knowledge and skills to understand, manage, and interact with AI systems effectively. This includes training in AI ethics, data privacy, and the interpretation of AI outputs.
  • Engaging with Regulators: Maintaining open lines of communication with regulatory bodies to understand their evolving expectations and to proactively share insights into the institution’s AI strategies and risk management practices.

The regulatory landscape surrounding AI in finance is dynamic and will continue to evolve. Financial institutions that prioritize transparency, accountability, and robust risk management in their AI implementations will be best positioned to navigate this complex environment, foster trust with their customers and regulators, and harness the transformative potential of AI responsibly. The era of AI in finance is here, and preparedness is no longer optional; it is an imperative for survival and success.

July 24, 2026 0 comment
0 FacebookTwitterPinterestEmail
FinTech Innovations

Brian Johnson Pledges Open Mind on CFPB Staffing Amidst Scrutiny Over Past Actions and Potential Conflicts

by admin July 24, 2026
written by admin

Brian Johnson, the Trump administration’s nominee to lead the Consumer Financial Protection Bureau (CFPB), stated on Thursday that he would commit to maintaining an "open mind about staffing levels" at the agency if confirmed. His remarks came during a pivotal hearing before the Senate Banking Committee, where he addressed questions concerning the bureau’s future under his potential leadership and his past professional associations.

"My understanding of the state of litigation is that I’ll have the opportunity to make those judgments," Johnson told senators, referring to a significant legal challenge currently impacting the CFPB’s workforce. This statement directly addresses a federal court ruling earlier this month that granted Johnson, should he be confirmed, a 60-day window to review a contentious plan that proposes a substantial reduction of the CFPB’s workforce by 53%.

The proposed cuts, which would eliminate approximately 618 positions, are part of a prolonged and contentious legal battle between the CFPB and the National Treasury Employees Union (NTEU), which represents the bureau’s employees. This dispute has been ongoing for 17 months, stemming from Acting Director Russ Vought’s aggressive efforts to either dismantle the agency or significantly downsize its operations. Vought’s tenure, which concludes on August 1st, has been marked by a series of actions aimed at reshaping the CFPB’s operational philosophy and scope.

A Shift in Direction Under Acting Director Vought

Under Acting Director Vought’s leadership, the CFPB has undergone a notable transformation. The agency has rescinded 67 pieces of previous guidance, a move that critics argue has weakened consumer protections. Furthermore, Vought has overseen the dropping of numerous enforcement actions and lawsuits, and the agency’s website has been systematically scrubbed of information pertaining to the actions and policies of previous administrations. This deliberate erasure of historical data has drawn criticism from consumer advocacy groups and Democratic lawmakers, who view it as an attempt to reframe the bureau’s legacy and potentially obscure past achievements in consumer protection.

When questioned by Senator Ruben Gallego (D-AZ) about whether he disagreed with any of Vought’s decisions, Johnson stated, "None come to mind at the moment." This response has been interpreted by some as an indication of alignment with Vought’s approach, or at least a reluctance to publicly critique the actions of his predecessor.

However, when pressed by Senator Chris Van Hollen (D-MD) on the prospect of eliminating the CFPB altogether, Johnson offered a different perspective. "That’s not my intention," he replied, emphasizing that the agency "is a creature of statute," acknowledging its congressionally mandated existence. This suggests that while Johnson may not seek to abolish the bureau, his approach to its operations and mandate could differ significantly from that of previous leadership.

Johnson’s Background and Potential Conflicts of Interest

President Donald Trump officially nominated Johnson to lead the CFPB in June. Johnson is no stranger to the agency, having served as its deputy director during Trump’s first term. More recently, since November 2024, he has held a position as a vice president and U.S. Card Compliance Officer at Capital One.

This recent employment at Capital One has become a central point of contention, particularly in light of the CFPB’s decision in February 2025 to drop a lawsuit against the very same bank. This action occurred less than a month after the bureau, under its then-Biden-era director, had initiated the lawsuit. The timing of these events has fueled concerns about potential conflicts of interest and whether Johnson’s past affiliation with Capital One could influence his oversight of the bank.

Senator Elizabeth Warren (D-MA), a key architect of the CFPB, has been a vocal critic, raising significant questions about Johnson’s nomination. In response to these concerns, Warren formally requested correspondence between Johnson and any CFPB employees dating back to November 2024, the period following his departure from the bureau and his commencement of employment at Capital One.

Warren also extended her inquiry to Capital One CEO Richard Fairbank last month, seeking clarity on Johnson’s potential involvement in the enforcement action or any advice he might have provided to Capital One regarding the lawsuit. Capital One responded by stating they were "not aware of any outreach by Mr. Johnson to the CFPB on Capital One’s behalf related to [the] lawsuit."

Allegations of Political Influence and "Corporate Pardon Machine"

Senator Warren has publicly asserted that the CFPB abandoned its lawsuit against Capital One shortly after the bank reportedly made a $1 million donation to support President Trump’s inauguration. This connection has led Warren to accuse the administration of operating a "corporate pardon machine," where financial firms that contribute to the President’s political endeavors allegedly benefit from the CFPB dropping enforcement actions against them. Warren pointed to 42 cases that were active when Trump took office and have since been settled, suggesting a pattern of favorable treatment for politically connected entities.

During the hearing, Warren posed a hypothetical scenario to Johnson: would he alert Congress or the Federal Reserve’s Inspector General if he discovered evidence of the White House pressuring the CFPB to drop an enforcement action against a donor company or suspend an investigation into a member of the Trump family? Johnson’s response, "With respect, I dispute the premise of the question," was met with a sharp retort from Warren, who interpreted it as a refusal to address potential corruption. "So the answer is no," she stated, adding, "You will not try to hose out the corruption." Warren concluded her questioning by alleging that the CFPB is being used as "an arm of President Trump’s ongoing corruption" and that Johnson’s stance suggests he would "keep that machine humming."

Johnson’s Stated Priorities and Vision for the CFPB

Despite the intense scrutiny, Johnson articulated his three primary priorities for the CFPB: protecting consumers, promoting accountability within the agency, and modernizing its operations. He expressed a nuanced view on the bureau’s role, stating, "Where the CFPB tries to remake markets according to an ideological agenda, it deprives consumers of choice, restricts their access to financial products and services, and drives up costs for providers which are ultimately borne by customers and investors." This statement suggests a potential shift away from what he might perceive as an overly expansive or activist approach, favoring a more market-oriented and efficiency-driven model.

Warren countered Johnson’s vision by referencing the proposed workforce reduction, specifically the significant cut in the number of examiners, from 350 to just 77. She questioned whether this reduction would make it "more or less likely that companies like your current employer – Capital One – will get away with hurting consumers." Johnson responded that the impact would depend on the CFPB’s "examination strategy," a response that did little to assuage Warren’s concerns about weakened oversight.

Recusal Agreement and Broader Context

In an effort to mitigate concerns about his tenure at Capital One, Johnson has pledged to recuse himself from any matters directly involving the bank for a period of two years, should he be confirmed. This agreement also includes provisions for Johnson to repay a portion of bonuses received from Capital One, though the bank has indicated he will not be required to repay any part of them. Warren wryly commented, "They must be really excited about getting you confirmed," implying that Capital One might be anticipating a more favorable regulatory environment under his leadership.

Johnson’s testimony before the Senate Banking Committee occurred one week after Acting Director Russ Vought appeared before the same panel. Vought reiterated his long-held view that the CFPB "remains structurally defective" and should not exist "in its current form." Johnson’s perspective, while acknowledging potential legislative deficiencies, presented a slightly different outlook. "The CFPB is capable of great good," he stated, but added, "I think there are deficiencies in the current legislative structure, and I have advocated in the past for changes to the CFPB’s authority and structure to ensure that it’s better able to execute its mission." This suggests a willingness to work within the existing statutory framework while advocating for reforms.

Related Nominations and Committee Actions

In related news from Thursday’s Senate Banking Committee session, the panel voted along party lines to advance the nomination of John Crews to serve on the board of the National Credit Union Administration (NCUA). Kyle Hauptman, the current chairman of the NCUA, has been nominated to join the Public Company Accounting Oversight Board (PCAOB). If confirmed, Crews would likely succeed Hauptman as the head of the NCUA. These other nominations underscore the broader efforts by the Trump administration to reshape regulatory bodies impacting the financial sector.

The confirmation process for Brian Johnson is expected to be closely watched, as it will likely signal the future direction of the CFPB and its approach to consumer protection in the financial industry. The nominee’s past affiliations, his responses to challenging questions, and the potential for continued legal and political battles will all play a significant role in shaping his legacy, should he be confirmed to lead the agency.

July 24, 2026 0 comment
0 FacebookTwitterPinterestEmail
NFT & Digital Assets

Transforming Intellectual Property into Digital Assets: The Strategic Shift Toward Onchain Brand Activation

by admin July 24, 2026
written by admin

In an era where consumer attention is the primary commodity, global brands are re-evaluating the utility of their intellectual property (IP). Traditionally confined to physical products, television advertisements, and seasonal campaigns, IP assets—including characters, logos, and proprietary narratives—are increasingly being repurposed as "digital collectibles." This evolution represents a fundamental transition from passive consumption to active digital ownership, as legacy corporations seek to bridge the gap between their historical catalogs and the emerging Web3 ecosystem. The most forward-looking brands are no longer merely protecting their IP through legal frameworks; they are activating it as "cultural currency" in a digital-first economy.

The shift toward digital assets is not a reactionary move to speculative trends but a calculated extension of brand equity. By converting iconic elements into digital products, companies are opening new engagement channels that deepen customer loyalty and provide tangible ownership to their most invested audiences. This strategic move is supported by robust market projections. The digital collectibles market, valued significantly in the early 2020s, is projected to grow from $11.25 billion in 2025 to over $48.6 billion by 2033. This represents a compound annual growth rate (CAGR) of 20.1%, signaling that the integration of blockchain technology into brand marketing is a long-term structural shift rather than a transient phenomenon.

The Evolution of Digital IP: From Speculation to Utility

To understand the current landscape, it is necessary to distinguish between the speculative "NFT craze" of 2021 and the current phase of IP-powered digital products. Early iterations of digital assets were often disconnected from established brand narratives, focusing instead on high-frequency trading and scarcity. Today, the focus has shifted toward utility and brand integration. Digital collectibles are now defined as IP-powered assets that unlock community engagement, reward long-term loyalty, and create multi-dimensional storytelling layers.

Bring Your Brand’s IP Onchain

These assets take various forms, ranging from digital twins of physical products to "access keys" for exclusive events. For a brand like Lamborghini, a digital collectible is not just a visual file; it is an entry point into a high-prestige ecosystem. For a consumer-facing giant like McDonald’s, it is a tool for mass-market engagement. The underlying technology—blockchain—serves as the ledger of authenticity, ensuring that the brand’s IP remains protected while allowing it to circulate in a global, 24/7 digital marketplace.

A Chronology of Institutional Adoption

The journey toward mainstream digital IP activation has followed a distinct timeline of institutional experimentation and refinement:

  1. The Experimental Phase (2020–2021): Early adopters like Nike and Adidas began acquiring digital-native studios or launching limited-edition drops to test the appetite for digital fashion and collectibles.
  2. The Infrastructure Build (2022–2023): Brands realized that third-party marketplaces often diluted their brand identity. This led to the rise of white-label solutions, where companies like Mattel and McFarlane Toys began building their own dedicated storefronts to control the user experience and maintain brand safety.
  3. The Mass Integration Phase (2024–Present): Digital assets are now being integrated into traditional marketing funnels. The recent partnership between McDonald’s and the NFT brand Doodles illustrates this. By launching over 100 million limited-edition "McCafé x Doodles" holiday cups across the United States, McDonald’s bridged the gap between a physical beverage purchase and a digital collectibles ecosystem, effectively onboarding millions of "normative" consumers into the digital asset space.

Case Studies in Digital IP Activation

Several industry leaders have already set the blueprint for successful IP activation, utilizing specialized infrastructure to ensure a seamless transition for their customer bases.

Mattel Creations: The Virtual Marketplace
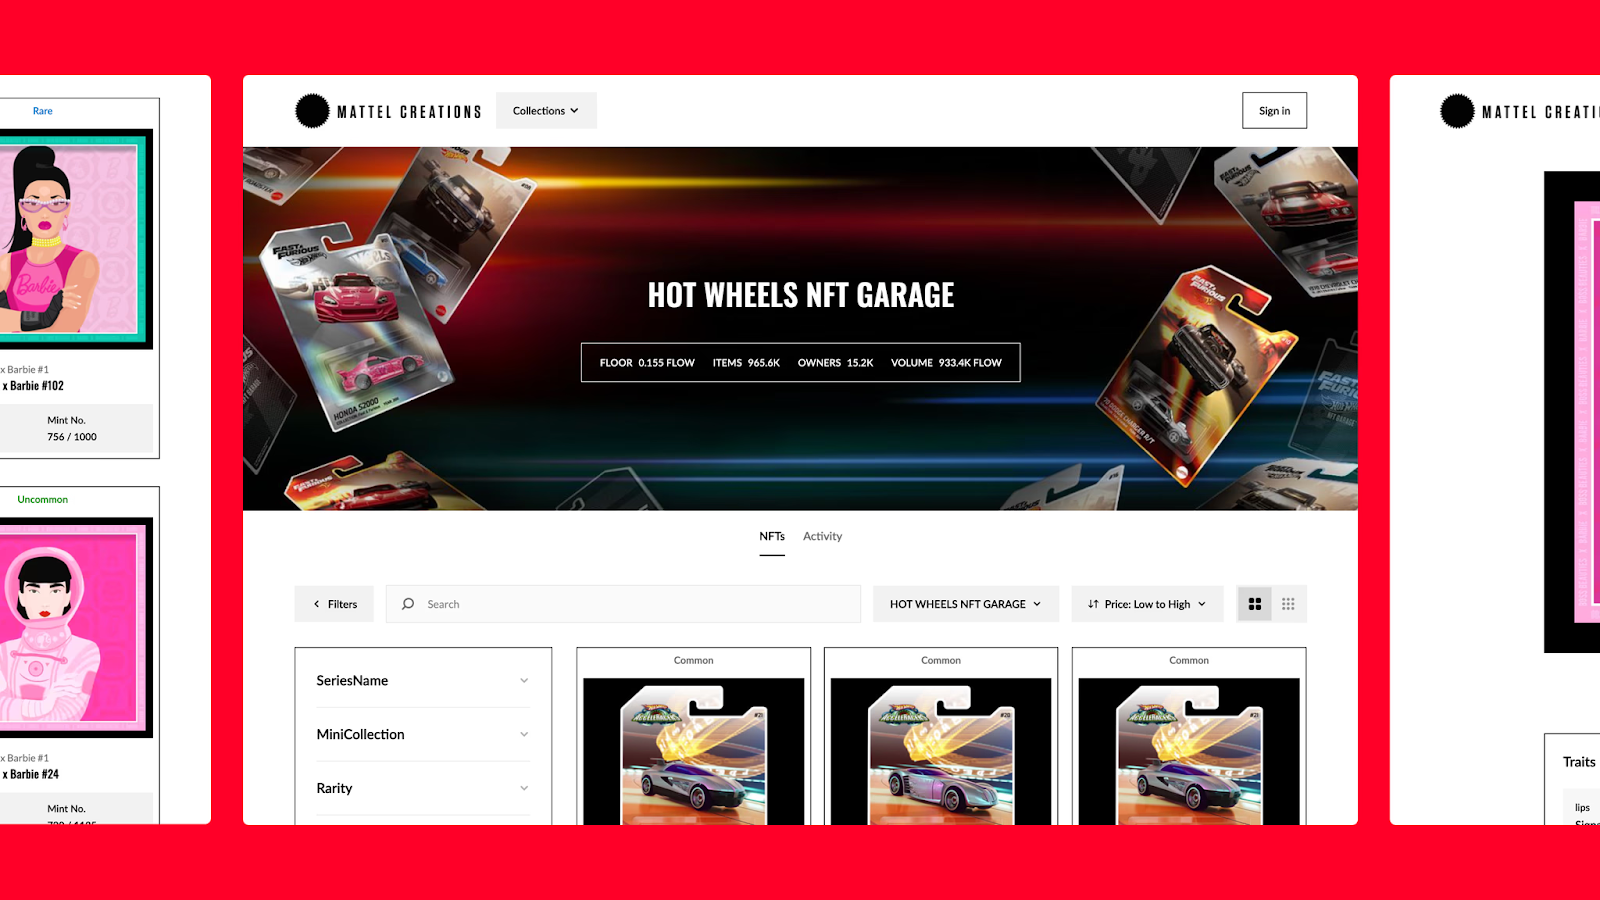
As one of the world’s largest toy manufacturers, Mattel possesses an unparalleled catalog of IP, including Barbie, Hot Wheels, and Masters of the Universe. To activate these assets, Mattel launched the Mattel Creations Virtual Marketplace. Built on the Flow blockchain, the platform was designed with a focus on "frictionless onboarding." By allowing fiat payments (credit card transactions) alongside crypto-native options, Mattel ensured that its traditional fan base could engage with digital collectibles without the technical hurdles typically associated with Web3. This strategy has allowed Mattel to create a secondary market for its IP, where fans can trade digital versions of rare toys, thereby extending the lifecycle of their products.

Bring Your Brand’s IP Onchain

McFarlane Toys: Engaging the Collector Community
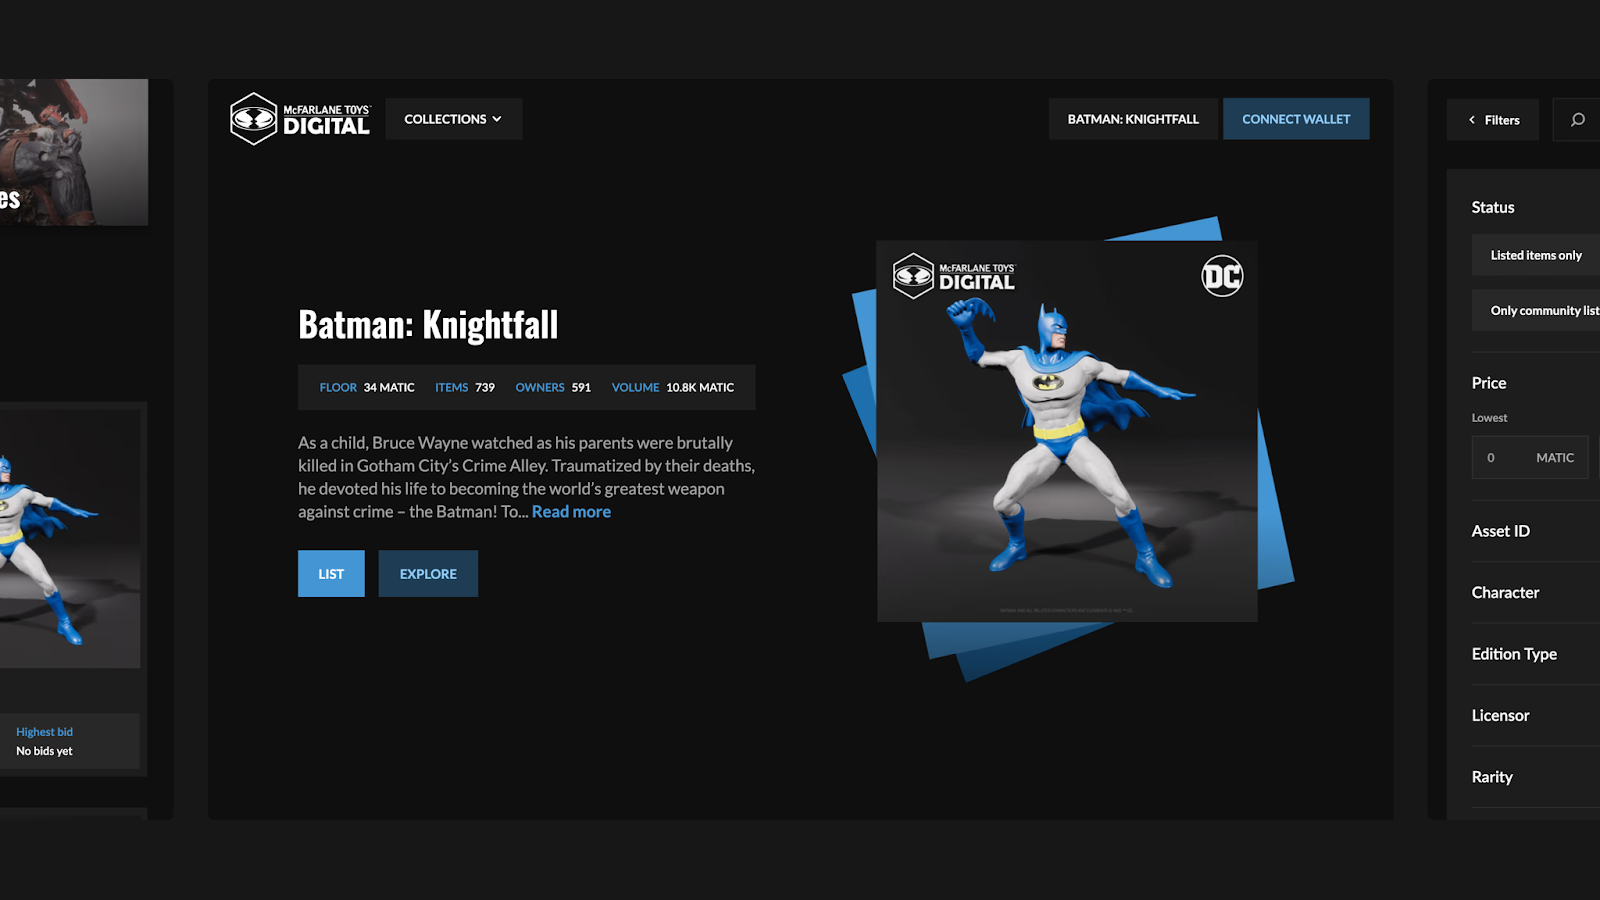
Known for highly detailed action figures and a dedicated collector base, McFarlane Toys partnered with RaribleX to launch a custom digital marketplace on the Polygon blockchain. The objective was twofold: to reach a younger, digitally native audience and to provide existing collectors with a new medium of engagement. By bringing their IP "onchain," McFarlane Toys created a verifiable ecosystem for digital figurines, mirroring the scarcity and collectibility of their physical counterparts.

Lamborghini: Scarcity and Prestige
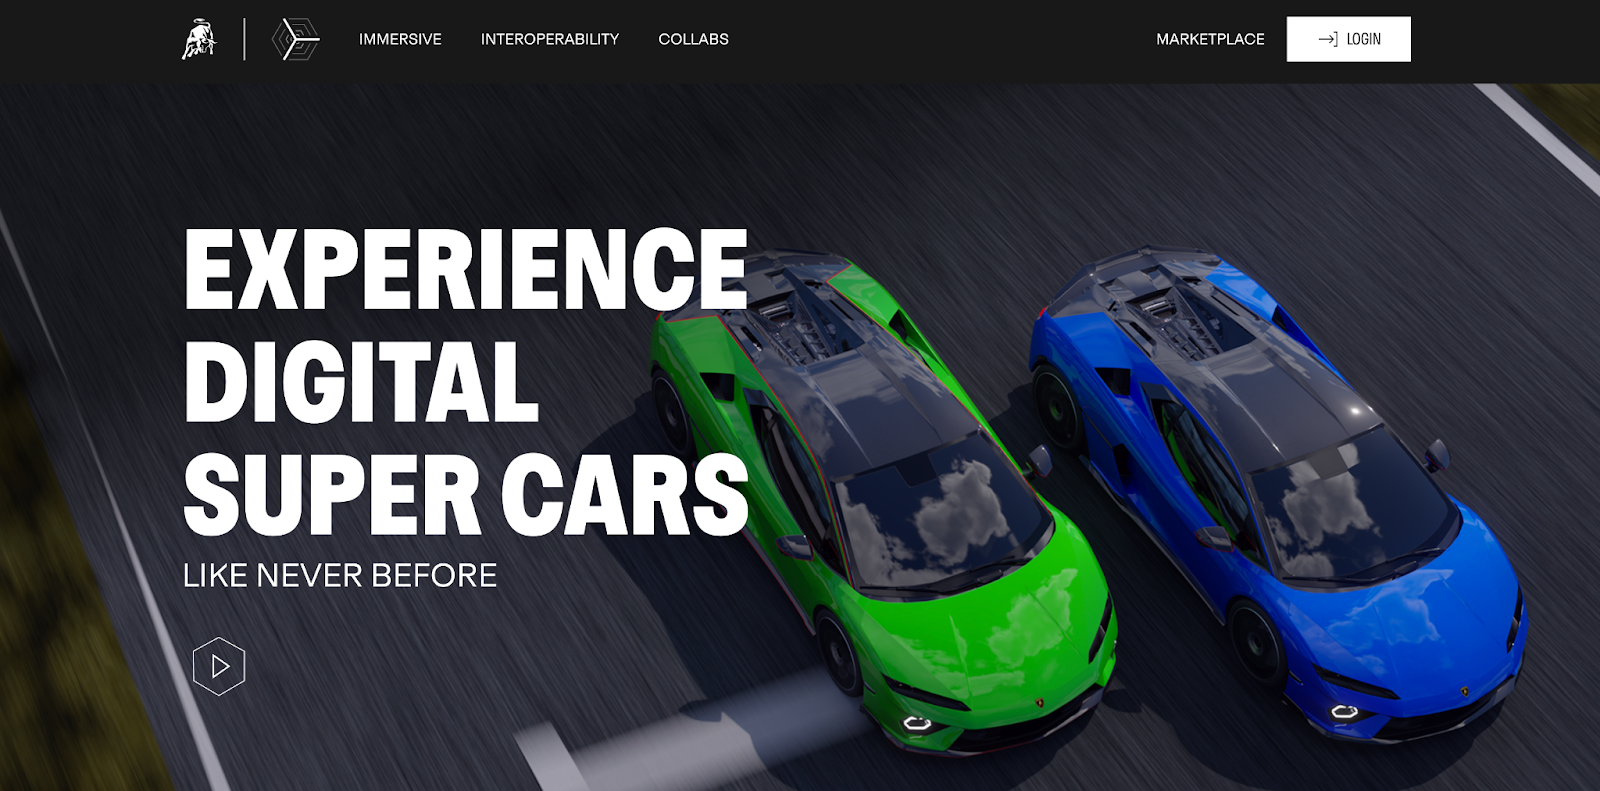
In the luxury sector, digital IP activation is used to reinforce exclusivity. Lamborghini’s digital marketplace, also powered by RaribleX, allows the automotive giant to release digital assets that reflect the engineering excellence and design heritage of the brand. These assets often serve as "digital keys" to exclusive experiences, bridging the gap between the virtual world and the high-performance reality of the brand.

Strategic Framework for IP Digitalization

For brands looking to enter the space, the process requires a structured approach to ensure the digital assets align with the core brand identity. Analysts suggest a five-step framework:

  1. IP Audit: Organizations must evaluate their existing assets—characters, slogans, legacy logos, and campaign milestones—to identify which elements hold the highest emotional or cultural value for their audience.
  2. Defining Purpose: The digital collectible must serve a clear function. Whether it is rewarding "super-fans," providing access to gated content, or acting as a loyalty token, the "utility" of the asset is what sustains its value over time.
  3. Format Selection: Brands must decide whether the IP is best represented as a static image, a 3D animation, an interactive file, or a "phygital" hybrid (a digital asset tied to a physical product).
  4. Experience Architecture: Maintaining brand safety is paramount. This involves creating a dedicated environment—such as a custom marketplace—where the brand controls the aesthetic, the rules of engagement, and the smart contracts.
  5. Activation and Lifecycle Management: Launching a digital asset is only the beginning. Successful brands use "limited drops," real-world rewards, and creative marketing hooks to ensure the IP remains relevant in the digital secondary market.

Technical Infrastructure and Brand Safety

The role of infrastructure providers like Rarible has become central to this shift. Unlike open, decentralized marketplaces that host a variety of content, brand-specific marketplaces allow corporations to maintain a "walled garden" approach. This ensures that their IP is not associated with unauthorized or inappropriate content.

Bring Your Brand’s IP Onchain

Key features of modern digital asset infrastructure include:

  • Custom Smart Contracts: Allowing brands to define royalty structures and secondary sale rules.
  • Seamless Onboarding: Utilizing "account abstraction" to allow users to sign up via email and pay with traditional currency, removing the need for complex digital wallets.
  • Multi-Chain Compatibility: Giving brands the flexibility to launch on blockchains that prioritize speed, low costs, or environmental sustainability (such as Polygon or Flow).

Broader Implications for the Global Market

The move toward digital IP activation has significant implications for the broader economy. First, it introduces a new revenue stream for legacy brands, particularly through secondary market royalties. Traditionally, once a physical product is sold, the manufacturer no longer profits from its subsequent resale. In the digital world, smart contracts allow the original IP holder to receive a percentage of every future transaction.

Second, it redefines the concept of a "loyalty program." Instead of points that expire, consumers hold digital assets that have potential value and can be traded or showcased. This creates a more dynamic relationship between the brand and the consumer, where the consumer is a "stakeholder" in the brand’s cultural success.

Finally, the digitalization of IP is forcing a modernization of intellectual property law. As digital assets cross international borders instantly, the need for global standards in digital ownership and copyright enforcement becomes more pressing.

Bring Your Brand’s IP Onchain

Conclusion: The Future of Cultural Currency

As the physical and digital worlds continue to converge, the "onchain" activation of intellectual property is becoming a necessity for brand longevity. Digital collectibles represent a new frontier for storytelling, community building, and value creation. By treating their IP as a living digital asset rather than a static relic, brands can ensure their relevance in the 21st-century marketplace.

The data suggests that the transition is well underway. With a projected market of nearly $50 billion by the early 2030s, the question for global brands is no longer whether to enter the digital asset space, but how to do so in a way that authentically reflects their heritage while embracing the possibilities of the future. Your IP is ready; the infrastructure is in place; the digital life of your brand has begun.

July 24, 2026 0 comment
0 FacebookTwitterPinterestEmail
Tech & Startup News

TechCrunch Disrupt 2026 Unveils Smart Money Stage to Explore the Intersection of Artificial Intelligence and Global Financial Infrastructure

by admin July 24, 2026
written by admin

The evolution of money has transcended the physical boundaries of cash and traditional bank accounts, entering an era defined by digital assets, autonomous agents, and real-time global connectivity. In recognition of this shift, TechCrunch Disrupt 2026 has announced the debut of the Smart Money Stage, a dedicated forum designed to examine the convergence of financial technology, payment systems, and artificial intelligence. Scheduled to take place from October 13 to 15 at the Moscone Center in San Francisco, the event will serve as a primary gathering point for industry leaders, founders, and investors to dissect the technological and regulatory frameworks currently reshaping the movement of value across the globe.

The introduction of the Smart Money Stage comes at a pivotal moment for the fintech industry. After a period of intense market correction and regulatory scrutiny, the sector is experiencing a resurgence driven by the integration of large language models (LLMs) and the maturation of blockchain-based settlement layers. The programming for this new stage will feature executives and innovators from prominent firms, including Circle, Robinhood, American Express, Plaid, and Airwallex, providing a comprehensive look at the infrastructure powering the modern economy.

A Historical Context of Financial Disruption

To understand the significance of the Smart Money Stage at Disrupt 2026, one must look at the trajectory of the fintech sector over the last decade. TechCrunch Disrupt has historically been the platform where major financial innovations were first introduced to a global audience. In the early 2010s, the focus was on the "unbundling" of traditional banks, giving rise to specialized apps for lending, saving, and investing. By the early 2020s, the industry shifted toward "embedded finance," where financial services were integrated into non-financial software platforms.

As we approach late 2026, the industry is entering what analysts call the "Autonomous Finance" era. This phase is characterized by the move away from manual financial management toward systems that utilize AI to make real-time decisions on behalf of consumers and corporations. The Smart Money Stage is a direct response to this evolution, moving beyond simple digital transactions to explore "smart" money—capital that is programmable, automated, and globally interoperable.

The Future of Money Movement and Programmable Assets

One of the central pillars of the Smart Money Stage is the transformation of payment rails. Traditional banking infrastructure, often reliant on decades-old systems like SWIFT or ACH, is increasingly being challenged by instant payment networks and stablecoins. Circle, the issuer of the USDC stablecoin, will be represented by Nikhil Chandhok, Chief Product and Technology Officer, to discuss the role of regulated digital currencies in the global economy.

The discussion will focus on how stablecoins provide a 24/7 settlement layer that operates independently of traditional banking hours. Supporting data indicates that the stablecoin market has grown significantly, with total market capitalization frequently exceeding $160 billion in recent years as institutional adoption increases. The session will compare these private-sector innovations with public-sector developments such as FedNow, the Federal Reserve’s instant payment service, and the various Central Bank Digital Currency (CBDC) pilots being conducted worldwide.

Joining the conversation will be Rodney Robinson, Co-founder and CEO of TabaPay, and Lotti Siniscalco, General Partner at Emergence. They are expected to address the technical challenges of achieving "interoperability"—the ability for different payment systems to communicate and exchange value seamlessly. The implications are vast: for businesses, this means reduced settlement times and lower transaction costs; for consumers, it means the end of the "pending transaction" era.

The Transformation of the Modern Financial Consumer

The way individuals interact with their wealth has undergone a radical shift, moving from static brokerage accounts to dynamic, multi-asset platforms. Robinhood, a company that has seen its market capitalization soar to more than $90 billion, stands as a primary example of this shift. Initially known as a commission-free trading app, Robinhood has expanded its services to include banking, credit, cryptocurrency, and even prediction markets.

Abhishek Fatehpuria, Robinhood’s Head of Product, will lead a session on "Winning the Modern Financial Consumer." This segment will explore how technology and changing consumer expectations are forcing financial institutions to adapt. As of 2026, the "modern consumer" expects a unified interface where they can manage a diverse portfolio of assets ranging from traditional stocks to digital tokens and high-yield cash accounts.

Analysis of the consumer landscape suggests that trust remains the most valuable currency. For platforms like Robinhood, maintaining this trust during periods of rapid growth and market volatility is a technical and operational challenge. The session will provide insights into how firms are using data analytics and user experience design to retain customers in an increasingly crowded marketplace.

AI, Trust, and the Rise of Agentic Finance

Perhaps the most anticipated theme of the Smart Money Stage is the role of Artificial Intelligence in financial services. The industry is moving beyond "Generative AI"—which focuses on creating content—toward "Agentic AI," where AI agents are empowered to take actions, such as executing trades, optimizing tax strategies, or negotiating bills.

This transition raises critical questions regarding oversight, security, and ethics. Panelists including Hannah Bozian of American Express, Pedro Sanzovo of Plaid, and Victoria Zuo of QED Investors will tackle the complexities of AI, trust, and verification. American Express has been a pioneer in using AI for fraud detection, while Plaid’s infrastructure connects thousands of apps to user bank accounts, making them a central player in the data verification ecosystem.

According to industry reports, fraud losses in the financial sector have continued to rise, reaching tens of billions of dollars annually. AI is being deployed as both a weapon by bad actors and a shield by financial institutions. The panelists will discuss how identity verification is evolving to combat "deepfake" fraud and how companies can ensure that AI agents operate within strict regulatory and ethical boundaries. The core of the debate centers on the "human-in-the-loop" philosophy: determining when an AI should be allowed to act autonomously and when human judgment must intervene.

Building Global Infrastructure for a Borderless Economy

The final major theme of the Smart Money Stage focuses on the infrastructure required for global commerce. Traditional financial systems were designed for a world of geographic borders and local currencies, but today’s digital economy is inherently global. Airwallex, a fintech unicorn valued at $11 billion, is at the forefront of building what it describes as an AI-native financial operating system.

Jack Zhang, Founder and CEO of Airwallex, will provide a deep dive into the requirements for building regulated financial infrastructure that serves millions of businesses. The challenge is twofold: technical and regulatory. To operate globally, a firm must navigate a patchwork of local regulations, anti-money laundering (AML) requirements, and "Know Your Customer" (KYC) protocols.

Zhang is expected to share how Airwallex utilizes AI to automate compliance and optimize cross-border currency exchanges. For many small and medium-sized enterprises (SMEs), accessing global markets was previously cost-prohibitive due to high banking fees and complex international regulations. Modern infrastructure providers are "democratizing" access to global trade by embedding these complex financial services directly into the software platforms that businesses use every day.

Chronology of Disrupt 2026 and Strategic Timing

The scheduling of TechCrunch Disrupt 2026 in mid-October is strategically timed to coincide with the final quarter of the fiscal year, a period when many firms set their budgets and strategic priorities for the coming year.

  • October 13: Opening of the event at the Moscone Center. The first day of the Smart Money Stage will focus on "The Future of Money Movement," setting the stage with discussions on payments and stablecoins.
  • October 14: The second day will shift toward the consumer and the application of AI, featuring the sessions with Robinhood, American Express, and Plaid.
  • October 15: The final day will focus on "Global Infrastructure" and the long-term implications of these technologies for the world economy.

This three-day sprint is designed to provide "signal over spin," a mantra that TechCrunch has adopted to ensure that the content remains grounded in technical reality rather than marketing hype.

Broader Impact and Industry Implications

The discussions held on the Smart Money Stage are expected to have ripple effects throughout the venture capital and startup ecosystems. For founders, the event provides a roadmap of where the "white space" exists in fintech—the areas where innovation is still needed, particularly in AI-driven security and cross-border settlement. For investors, the event offers a glimpse into which technologies are moving from the "experimental" phase to "production-ready" status.

The convergence of AI and fintech also has significant implications for traditional banking institutions. As fintech firms build more robust, AI-native infrastructure, legacy banks face increasing pressure to modernize their tech stacks or risk becoming "dumb pipes"—entities that hold deposits but lose the customer relationship to more agile technology platforms.

Furthermore, the regulatory environment in 2026 continues to be a major factor. With the implementation of frameworks like MiCA (Markets in Crypto-Assets) in Europe and evolving guidelines from the SEC and CFPB in the United States, the Smart Money Stage will serve as a venue for discussing how innovation can coexist with consumer protection.

In conclusion, TechCrunch Disrupt 2026’s Smart Money Stage represents a comprehensive effort to map the future of the financial world. By bringing together the architects of the new payment rails, the leaders of consumer platforms, and the experts in AI security, the event aims to provide a clear-eyed view of how money will move, grow, and be protected in the years to come. As the pricing window for tickets approaches its close, the industry’s focus turns to San Francisco, where the next chapter of financial technology will be written.

July 24, 2026 0 comment
0 FacebookTwitterPinterestEmail
Tech & Startup News

Paramount Skydance and Warner Bros Discovery Agree to Extended Merger Delay Until 2027 Amid Multi State Antitrust Litigation

by admin July 24, 2026
written by admin

In a significant development for the global media landscape, Paramount Skydance and Warner Bros. Discovery (WBD) have formally agreed to a protracted delay of their proposed $111 billion merger. The agreement, finalized through a court-filed stipulation, ensures that the two entertainment giants will not complete their transaction or integrate their sprawling operations until at least June 1, 2027, or until five days after a federal judge issues a final ruling on the merits of a multi-state antitrust lawsuit. This move effectively freezes one of the largest proposed consolidations in the history of the American film and television industry, providing a substantial window for legal scrutiny into the deal’s potential impact on competition and consumer choice.

The legal standstill follows a concerted effort by a coalition of 12 states, led by California and New York, to block the merger on the grounds that it violates federal antitrust laws. The Writers Guild of America (WGA), which represents thousands of content creators, joined the opposition with its own lawsuit, further complicating the path to closure for Paramount and Skydance. Under the terms of the new agreement, if a judicial determination on the merits of the case has not been reached by the June 2027 deadline, the plaintiffs—including the various state attorneys general and the WGA—reserve the right to seek a preliminary injunction to maintain the block on the deal.

The Legal Framework of the Stay

The stipulation filed in the U.S. District Court for the Northern District of California represents a strategic pause in what has become a high-stakes battle over the future of Hollywood. Judge Araceli Martínez-Olguín, who is presiding over the case, previously granted a temporary restraining order (TRO) against the merger, signaling that the court found merit in the states’ arguments that the deal could "substantially reduce competition."

By agreeing to this "months-long halt," the companies have avoided an immediate, potentially more damaging preliminary injunction hearing while securing a "direct path to a trial." This procedural maneuver allows both the corporate entities and the opposing states to prepare their evidence for a full trial on the merits. For the states, the delay is a "critical victory," as described by New York Attorney General Letitia James, ensuring that the status quo remains while the court examines the complexities of the $111 billion transaction.

Historical Context: A Contentious Path to Consolidation

The proposed merger between Paramount Skydance and Warner Bros. Discovery did not emerge in a vacuum. It follows a period of intense volatility in the media sector, characterized by the "streaming wars" and a frantic race for scale. Paramount Global, the parent company of CBS, MTV, and Paramount Pictures, had been the subject of acquisition rumors for years as its controlling shareholder, the Redstone family via National Amusements, sought a viable exit strategy or a partner to help navigate the decline of linear television.

The entry of Skydance Media, led by David Ellison, into the fray initially appeared to be the resolution Paramount was seeking. However, the subsequent pivot toward a massive $111 billion combination with Warner Bros. Discovery—itself a product of a recent merger between WarnerMedia and Discovery Inc.—raised immediate red flags among regulators and industry watchdogs.

The deal received a surprising "green light" from the Trump administration, a move that reportedly stunned staff lawyers at the U.S. Department of Justice (DOJ). Reports indicate that DOJ career professionals had been leaning toward recommending a lawsuit to block the deal, citing many of the same concerns now being raised by the 12 states. The disconnect between the federal executive branch’s approval and the career staff’s skepticism provided the opening for state attorneys general to step in and exercise their independent authority to enforce antitrust statutes.

Antitrust Concerns: The "Big Five" and Cable Dominance

The core of the states’ legal challenge rests on the assertion that the merger would eliminate critical competition by combining two of the "Big Five" major Hollywood movie studios. In the modern era, the major studios—Disney, Warner Bros., Universal, Sony, and Paramount—control the vast majority of high-budget film production and global distribution. Reducing this number to four, the states argue, would create an oligopoly with the power to dictate terms to exhibitors, talent, and secondary distributors.

Beyond the silver screen, the merger poses significant questions regarding the cable television market. Warner Bros. Discovery and Paramount are two of the five largest owners of basic cable channels in the United States. Their portfolios include household names such as CNN, HBO, TNT, TBS, and Food Network (under WBD), and CBS, Nickelodeon, MTV, Comedy Central, and BET (under Paramount).

Industry analysts point out that a combined entity would hold unprecedented leverage in negotiations with cable and satellite providers (MVPDs). This "bundling power" could lead to higher carriage fees, which are ultimately passed on to consumers in the form of higher monthly cable bills. Furthermore, the merger would consolidate two of the most significant players in the burgeoning streaming market—Max and Paramount+—potentially leading to reduced content spending and higher subscription prices as the combined entity seeks to achieve profitability.

Stakeholder Reactions and Competing Narratives

The announcement of the delay was met with vastly different interpretations from the parties involved. For the state attorneys general, the agreement is a validation of their role as protectors of the marketplace.

"Halting this merger while our case proceeds is a critical victory in our efforts to uphold the law and protect the film and television industries," stated New York Attorney General Letitia James. Her office emphasized that the pause prevents "irreparable harm" to the industry while the legal process unfolds. California Attorney General Rob Bonta echoed this sentiment, expressing eagerness to "continue to make our case in court and celebrate another tremendous win in our effort to ensure this unlawful merger never sees the light of day."

Conversely, Paramount has framed the delay not as a setback, but as a strategic win. In statements to media outlets, the company claimed the result is exactly what it sought: a clear path to a trial based on evidence rather than speculation. Paramount maintains that the transaction is "good for competition, good for consumers, and good for creators." The company’s legal team has pointed to approvals from "dozens of competition authorities around the world" as evidence that the merger is sound. From Paramount’s perspective, a trial is the fastest way to dispel the states’ concerns and prove that the merger is necessary for the companies to remain competitive against tech giants like Netflix, Amazon, and Apple.

Labor and the Creative Community

The involvement of the Writers Guild of America adds a crucial labor dimension to the litigation. The WGA’s opposition is rooted in the fear of "monopsony"—a market condition where there are so few buyers (employers) that they can suppress the prices paid to sellers (creators).

In a consolidated Hollywood, writers and showrunners would have fewer doors to knock on to get their projects greenlit. The WGA has long argued that the wave of media consolidation over the last decade has led to smaller writers’ rooms, shorter episode orders, and a decline in residual payments. By blocking the WBD-Paramount merger, the WGA aims to preserve a diverse ecosystem of buyers, which they argue is essential for both the economic health of their members and the creative vibrancy of the industry.

Chronology of the Paramount-Skydance-WBD Merger Saga

  • Early 2024: Rumors intensify regarding Paramount Global’s search for a strategic partner or buyer amid declining linear TV revenues.
  • Spring 2024: Skydance Media emerges as a primary suitor, engaging in exclusive talks with National Amusements.
  • Late Spring 2024: The scope of the deal expands to include a massive consolidation involving Warner Bros. Discovery, with a total valuation estimated at $111 billion.
  • June 2024: The Trump administration’s Department of Justice officially greenlights the merger, despite reported internal dissent from career antitrust lawyers.
  • July 2024: A coalition of 12 states, led by California and New York, files a lawsuit in the Northern District of California to block the merger.
  • July 21, 2024: Judge Araceli Martínez-Olguín issues a temporary restraining order (TRO), halting the deal’s progress.
  • July 24, 2024: Paramount, WBD, the 12 states, and the WGA sign a stipulation to delay the merger until June 1, 2027, or until a merits determination is reached.

Economic Implications and Industry Outlook

The $111 billion valuation of this deal makes it one of the most complex financial undertakings in media history. Both Paramount and Warner Bros. Discovery carry significant debt loads—a legacy of previous acquisitions and the high cost of building streaming infrastructure. Critics of the merger argue that the combined company would be forced to engage in aggressive cost-cutting, including layoffs and the cancellation of niche or experimental programming, to service its debt.

From a broader economic perspective, the case is being watched as a bellwether for the future of antitrust enforcement in the United States. For decades, federal regulators largely focused on "consumer welfare," often defined narrowly as the impact on prices. However, the current challenge by the states reflects a broader "neo-Brandeisian" approach, which considers the impact of consolidation on labor, innovation, and the overall health of the democratic "marketplace of ideas."

If the states are successful in permanently blocking the merger, it could signal the end of the era of mega-mergers in Hollywood. Companies may be forced to look toward smaller, bolt-on acquisitions or internal restructuring rather than massive horizontal integrations.

The Road to 2027

The agreement to halt operations until 2027 creates a period of prolonged uncertainty for the employees, shareholders, and partners of both Paramount and Warner Bros. Discovery. For the next three years, these companies must continue to operate as fierce competitors while their long-term future remains tied to the outcome of a courtroom battle.

This "limbo" period will likely see both firms continue to pivot their strategies. Warner Bros. Discovery, under the leadership of David Zaslav, will continue its focus on debt reduction and the global expansion of its Max streaming service. Paramount, meanwhile, must find ways to stabilize its linear business and grow Paramount+ without the immediate safety net of a WBD partnership.

The trial, when it eventually occurs, will be a landmark event. It will feature expert testimony on market definitions, the elasticity of consumer demand for cable packages, and the intricacies of film distribution. Until then, the Hollywood landscape remains in a state of suspended animation, with the "Big Five" remaining intact for at least another few years. The outcome of this case will not only determine the fate of these two companies but will likely define the regulatory boundaries of the entertainment industry for a generation.

July 24, 2026 0 comment
0 FacebookTwitterPinterestEmail
Tech & Startup News

Lanterns Trailer Hal Jordan and John Stewart Team Up for a Manhunter Murder Mystery.

by admin July 24, 2026
written by admin

The landscape of superhero television underwent a seismic shift at San Diego Comic-Con as HBO unveiled the first official trailer for Lanterns, the highly anticipated series centered on the Green Lantern Corps. This new iteration of the storied DC Comics property marks a significant departure from previous adaptations, leaning into a gritty, grounded procedural tone that has already drawn comparisons to prestige crime dramas like True Detective. Set within the newly minted DC Universe (DCU) spearheaded by James Gunn and Peter Safran, Lanterns introduces a world where intergalactic law enforcement meets small-town secrets, anchored by the powerhouse duo of Kyle Chandler and Aaron Pierre.

The trailer, which debuted to a packed Hall H audience, establishes the core dynamic between the two leads: Hal Jordan (Chandler) and John Stewart (Pierre). Unlike the high-flying, space-faring adventures often associated with the characters, this series grounds the action in the American heartland. Hal Jordan is presented as a seasoned, perhaps world-weary veteran of the Green Lantern Corps—a legend who has seen the furthest reaches of the galaxy but now finds himself tethered to a mystery on his home turf. In contrast, John Stewart is the disciplined newcomer, a recruit whose rigid military background clashes with Hal’s more improvisational, and at times abrasive, mentorship style.

A Neo-Western Approach to Cosmic Justice

The aesthetic of Lanterns is intentionally distinct. Co-creators Chris Mundy, Damon Lindelof, and Tom King have crafted a narrative that prioritizes atmosphere and character tension over pure spectacle. The trailer highlights a "neo-Western" flair, utilizing the vast, isolated landscapes of middle America to mirror the isolation of space. This stylistic choice is a deliberate move to reinvent the Green Lantern brand, which has struggled to find its footing in live-action since the 2011 feature film.

The central conflict of the first season revolves around a grisly murder investigation. However, this is no ordinary homicide. The clues point toward a connection with the Manhunters, an ancient and fearsome race of self-evolving robots that served as the predecessors to the Green Lantern Corps before they turned genocidal. By integrating the Manhunters into a terrestrial murder mystery, the writers are bridging the gap between street-level detective work and the sprawling mythology of the DC cosmic pantheon.

The trailer showcases several key moments of friction between the leads. In one standout scene, Hal Jordan is seen dumping a bucket of water on a sleeping John Stewart, a move that underscores the "strained" relationship mentioned by early reviewers. The power dynamic is clear: Hal is the authority, and John is the "backup," a label that clearly grates on the younger Lantern. Yet, the trailer also teases the growth of John’s abilities. While Hal effortlessly maneuvers through the sky using his power ring, John is shown creating a delicate, glowing hummingbird—a construct that suggests a level of precision and untapped potential that may eventually surpass his mentor.

Casting and Creative Pedigree

The casting of Kyle Chandler and Aaron Pierre has been met with widespread acclaim. Chandler, known for his Emmy-winning role in Friday Night Lights, brings a "grizzled mentor" energy that fits the veteran Hal Jordan perfectly. Aaron Pierre, whose star has risen rapidly following performances in Rebel Ridge and The Underground Railroad, provides a stoic, commanding presence as John Stewart. Their chemistry is the engine of the series, providing a human anchor to the fantastical elements of the plot.

The supporting cast is equally impressive, featuring a blend of industry veterans and rising stars. The trailer confirms appearances by Nathan Fillion, reprising his role as Guy Gardner from the upcoming Superman film, further cementing the interconnected nature of the DCU. Ulrich Thomsen appears as Sinestro, the iconic antagonist whose relationship with Hal Jordan is one of the most complex in comic book history. The cast also includes Kelly Macdonald, Garret Dillahunt, Poorna Jagannathan, Laura Linney, Jason Ritter, J. Alphonse Nicholson, and Jasmine Cephas Jones, suggesting a deep ensemble that will flesh out the civilian and cosmic sides of the story.

Behind the camera, the creative team represents a "dream team" for prestige television. Chris Mundy served as the showrunner for the critically acclaimed Ozark, bringing a mastery of tension and moral ambiguity. Damon Lindelof is the architect behind HBO’s Watchmen and The Leftovers, known for his ability to deconstruct superhero tropes and explore profound existential themes. Tom King, one of the most celebrated modern comic book writers, provides the foundational lore, ensuring the series remains true to the spirit of the source material while forging a new path.

'Lanterns' trailer: Hal Jordan and John Stewart team up for a Manhunter murder mystery

The Chronology of Development

The journey of Lanterns to the screen has been a long and transformative process. Initially conceived under a previous administration at DC as a more traditional, big-budget space opera produced by Greg Berlanti, the project was completely overhauled when James Gunn and Peter Safran took the reins of DC Studios in late 2022.

  • January 2023: James Gunn officially announces Lanterns as part of "Chapter 1: Gods and Monsters." He describes it as a "True Detective-type mystery" that plays a foundational role in the overarching DCU story.
  • Early 2024: The creative team of Mundy, Lindelof, and King is finalized, signaling a shift toward a more grounded, character-driven narrative.
  • Mid-2024: Casting begins in earnest, with Aaron Pierre winning the role of John Stewart after a highly publicized search. Shortly thereafter, Kyle Chandler is confirmed as Hal Jordan.
  • Late 2024 – Early 2025: Principal photography takes place on location and in specialized studios, focusing on practical effects complemented by high-end CGI for the Lantern constructs.
  • July 2026: The first trailer is released at San Diego Comic-Con, setting a premiere date of August 16, 2026.

Strategic Implications for the DC Universe

Lanterns is more than just a standalone series; it is a critical pillar of the new DCU strategy. Unlike the previous "DCEU," which often prioritized interconnected movie events, Gunn’s DCU treats television as an equal partner in world-building. Lanterns is expected to introduce "the ancient horror" that will serve as a recurring threat across multiple films and series.

Furthermore, the show represents HBO’s continued commitment to high-concept "appointment television." By branding the series as an HBO Original rather than a Max Original, the network is signaling that Lanterns carries the same prestige and production value as The Last of Us or House of the Dragon. This move is designed to attract a broader audience beyond the traditional superhero fanbase, appealing to viewers who enjoy complex procedurals and character studies.

The inclusion of the Manhunters is a particularly astute narrative choice. In DC lore, the Manhunters were the Guardians of the Universe’s first attempt at an interstellar police force. Their failure—and the subsequent "Massacre of Sector 666"—led to the creation of the Green Lantern Corps. By bringing this history to the forefront, Lanterns explores themes of systemic failure, the evolution of justice, and the dangers of absolute power.

Official Reactions and Industry Outlook

While official reviews are still under embargo, the reaction from the Comic-Con crowd was overwhelmingly positive. Industry analysts suggest that Lanterns could be the project that finally "breaks the curse" of the Green Lantern on screen. The decision to move away from the "willpower vs. fear" color-coded battles of the 2011 film in favor of a detective story is being hailed as a masterstroke.

"The goal was to make a show where the rings are a part of their lives, but their minds are their greatest tools," said a source close to the production during a post-panel press briefing. "Hal and John aren’t just superheroes; they are detectives. They have to talk to witnesses, analyze evidence, and navigate local politics. The cosmic stuff is the backdrop to a very human story."

As the August 16 premiere approaches, the marketing campaign for Lanterns is expected to ramp up, focusing on the mystery at the heart of the show. With a prime Sunday night slot on HBO, the series is positioned to be the television event of the summer.

Lanterns premieres Aug. 16 at 9 p.m. ET on HBO and will be available for streaming on Max. The first season is expected to consist of eight episodes, airing weekly, as the mystery of the Manhunters and the heartland murder unfolds, potentially changing the face of the DC Universe forever.

July 24, 2026 0 comment
0 FacebookTwitterPinterestEmail
Artificial Intelligence & Tech

Advancing Large Language Model Reliability: An In-Depth Analysis of Amazon’s GraphEval Framework for Hallucination Detection

by admin July 24, 2026
written by admin

The rapid proliferation of large language models (LLMs) across enterprise and consumer sectors has brought the issue of "hallucinations" to the forefront of artificial intelligence research. Hallucinations occur when an LLM generates a response that is factually incorrect, logically inconsistent, or entirely fabricated, often due to limitations in the model’s internal knowledge or errors in the probabilistic token-prediction process. While the industry has made significant strides in improving the generative capabilities of these models, the development of robust, explainable, and methodological frameworks for diagnosing and evaluating these errors has lagged behind. In response to this challenge, researchers at Amazon have proposed a novel evaluation framework known as GraphEval. This methodology utilizes knowledge graphs to provide a granular, transparent analysis of LLM outputs, moving beyond traditional scoring metrics to offer a localized "map" of where specific factual breakdowns occur.

The Problem of Hallucination in Modern AI Systems

As LLMs like GPT-4, Claude, and Llama 3 are integrated into critical workflows—ranging from medical diagnosis assistance to financial forecasting—the cost of factual errors has escalated. Industry data suggests that hallucination rates can vary significantly depending on the task; for example, in summarization tasks, hallucination rates have been observed between 3% and 10%, while in creative or open-ended generation, the rate can climb as high as 27%.

Current evaluation methods often rely on metrics such as BLEU, ROUGE, or BERTScore. While these are useful for measuring linguistic similarity or semantic overlap between a model’s output and a reference text, they frequently fail to capture factual accuracy. A model could produce a sentence that is grammatically perfect and semantically similar to the source material while still containing a critical factual error. Furthermore, many existing "black-box" evaluation tools provide a single numerical score without explaining why a specific passage was flagged as inaccurate. This lack of transparency makes it difficult for developers to debug models or for enterprises to trust AI-generated insights.

GraphEval: A Two-Stage Knowledge-Based Approach

The GraphEval framework, as detailed in recent research from Amazon Science, addresses the limitations of traditional metrics by introducing a structured, two-stage process that leverages the formal logic of knowledge graphs (KGs). By converting unstructured text into a series of interconnected nodes and edges, the framework allows for a precise comparison between the model’s claims and a verified ground-truth context.

The methodology operates through two distinct phases: Knowledge Graph Extraction and Natural Language Inference (NLI) Verification.

Stage 1: Knowledge Graph Extraction

In the first stage, the framework processes the LLM-generated response to identify its core factual claims. These claims are extracted in the form of "triples"—a standard data structure in knowledge representation consisting of a Subject, a Relationship, and an Object (e.g., "GraphEval," "uses," "Knowledge Graphs"). By decomposing a complex paragraph into these atomic units of information, the framework strips away linguistic flourishes and focuses solely on the underlying assertions. In a production environment, this extraction is typically performed by an auxiliary, highly accurate "evaluator" model or a specialized information extraction pipeline.

Stage 2: Fact Verification via Natural Language Inference

Once the triples are extracted, they must be validated against a "ground truth" source. This source context is usually derived from a vector database in a Retrieval-Augmented Generation (RAG) system or a curated internal knowledge base. GraphEval utilizes a Natural Language Inference (NLI) model to compare each triple against the source context.

The NLI model categorizes the relationship between the ground truth and the triple into three categories:

  1. Entailment: The ground truth supports the claim.
  2. Neutral: The ground truth neither supports nor contradicts the claim.
  3. Contradiction: The ground truth directly refutes the claim.

In the GraphEval framework, any triple that does not result in an "entailment" classification is flagged as a hallucination. This binary threshold ensures that only information explicitly supported by the source data is permitted, a critical requirement for high-stakes enterprise applications.

Technical Implementation and Simulation

To understand the practical utility of GraphEval, one can look at a simulated implementation using open-source tools such as the Hugging Face transformers library, networkx for graph construction, and the DeBERTa-v3 model for NLI tasks.

Language Model Hallucination Evaluation with GraphEval - KDnuggets

Consider a scenario where an LLM is asked to define GraphEval. The model might generate a response that correctly identifies its purpose but incorrectly claims it requires an "expensive enterprise server farm" to operate. A human reader might miss this nuance, but the GraphEval framework identifies it through systematic decomposition.

The extraction process would yield three triples:

  1. (GraphEval, is, evaluation framework)
  2. (GraphEval, uses, Knowledge Graphs)
  3. (GraphEval, requires, expensive enterprise server farm)

When these are compared against the actual research paper (the ground truth), the first two triples result in "entailment." However, because the research paper makes no mention of hardware requirements, the third triple is labeled "neutral." Under the GraphEval logic, this is flagged as a hallucination.

The final component of the framework is visualization. By using libraries like matplotlib, developers can generate a "Hallucination Map." In this visual representation, grounded facts are connected by green edges, while hallucinated claims are connected by red edges. This provides immediate, interpretable feedback on exactly which part of the model’s response is untrustworthy.

Chronology of Hallucination Detection Research

The development of GraphEval represents a significant milestone in a decade-long effort to make AI more reliable.

  • 2014–2018: Early research focused on "word overlap" metrics. These were sufficient for early translation models but failed as LLMs became more sophisticated.
  • 2019–2021: The rise of Transformer models led to the development of BERTScore and other embedding-based metrics. While better at understanding meaning, they remained "black boxes."
  • 2022: The "ChatGPT moment" made hallucination a household term, leading to the development of SelfCheckGPT, which uses multiple model iterations to check for consistency.
  • 2023–2024: Researchers shifted toward "External Verification" frameworks. Amazon’s GraphEval (2024) represents the current frontier, moving away from simple consistency checks toward structured, knowledge-based verification.

Industry Implications and Broader Impact

The implications of the GraphEval framework extend far beyond academic research. In the corporate world, the "black box" nature of AI has been a primary barrier to adoption.

Legal and Compliance: For legal departments, GraphEval offers an audit trail. If an AI-generated contract summary contains an error, the framework can show exactly which sentence was hallucinated and which source document it failed to align with. This level of traceability is essential for meeting regulatory requirements like the EU AI Act.

Cost Efficiency: While running an LLM for every evaluation can be expensive, the GraphEval approach allows for the use of "Small Language Models" (SLMs) for the NLI stage. Models like DeBERTa-v3-small are computationally lightweight and can be run locally, significantly reducing the cost of continuous monitoring in production environments.

Developer Productivity: By localizing errors to specific triples, GraphEval allows developers to perform "root cause analysis." If a model consistently hallucinates about a specific topic, developers can identify whether the issue lies in the retrieval step (the wrong documents are being fed to the model) or the generation step (the model is ignoring the provided context).

Conclusion and Future Outlook

Amazon’s GraphEval framework highlights a critical shift in the AI industry: the move from "bigger models" to "better oversight." As LLMs continue to integrate into the fabric of global infrastructure, the ability to detect and visualize errors becomes as important as the ability to generate text. By marrying the structural rigor of knowledge graphs with the semantic power of NLI models, GraphEval provides a scalable, explainable solution to the hallucination problem.

The future of this research likely involves "real-time" GraphEval integration, where the framework acts as a filter, catching hallucinations before they ever reach the end-user. As these diagnostic tools become more sophisticated, the "black box" of AI will continue to become more transparent, paving the way for safer and more reliable autonomous systems. In the words of the research community, the goal is no longer just to make models smarter, but to make them more accountable.

July 24, 2026 0 comment
0 FacebookTwitterPinterestEmail
Artificial Intelligence & Tech

The Rise of Tabular Foundation Models and the Disruption of Traditional Machine Learning Benchmarks

by admin July 24, 2026
written by admin

For more than a decade, the consensus in the data science community has remained largely unshaken: if you are working with tabular data, you use gradient-boosted decision trees. This "default answer" has seen libraries like XGBoost, LightGBM, and CatBoost dominate Kaggle competitions and enterprise production environments alike. However, recent developments in the field of "Tabular Foundation Models" (FMs) are fundamentally inverting this paradigm. According to the latest data from TabArena, a prominent community benchmark, every single-model entry currently outperforming the most highly tuned gradient-boosted trees is a pretrained transformer. These models, loosely categorized as "tabular LLMs," are now demonstrating the ability to predict missing columns or labels in any spreadsheet with zero-shot accuracy, mimicking the way a large language model completes a sentence.

The emergence of these models represents a shift from traditional training-heavy workflows toward in-context learning. In this new framework, the step previously known as "training"—which involved extensive hyperparameter optimization and gradient descent—is replaced by a single forward pass during inference. This evolution was recently put to the test through an independent audit of TabICLv2, one of the strongest open-weight models in this class. The audit, conducted on independent hardware, confirmed that these models are not only statistically superior in accuracy on diverse datasets but are also significantly more efficient in terms of setup time and computational cost.

The Architecture of In-Context Learning for Tables

A tabular foundation model is a pretrained transformer designed to treat a spreadsheet as a context-rich environment rather than a static dataset. Unlike a text-based LLM, which processes word-pieces from a fixed vocabulary, a tabular model works with raw numerical and categorical cells. Because every table has unique columns and features, the model must be capable of inferring relationships on the fly.

Tabular LLMs: An Introduction to the Foundation Models That Predict Your Spreadsheet

TabICLv2, a leading example of this architecture developed by Inria’s SODA team, utilizes a three-stage transformer process to achieve this. The first transformer acts as a set transformer, reading down columns to understand the distribution of values. This allows the model to differentiate between identical numbers used in different contexts—for instance, recognizing that "450" in a price column represents a different statistical entity than "450" in a postal code column.

The second stage processes across rows, collapsing the features of a single entry into a fixed-length vector. Finally, the third transformer performs the actual prediction via in-context learning. During this phase, unlabelled test rows attend to labelled training rows provided in the "prompt." The model identifies patterns and similarities, effectively performing a highly sophisticated, learned version of k-nearest-neighbors. This eliminates the need for gradient-based training on the user’s specific data, as the model’s weights are already tuned to understand general tabular structures through pretraining on millions of synthetic tables.

Chronology of Development: From TabPFN to TabFM

The timeline of this technological shift began in earnest in 2022 with the release of TabPFN (Tabular Prior-Data Fitted Network). Developed by Prior Labs, TabPFN established the feasibility of using transformers for in-context learning on small-to-medium-sized tables. This was followed by a rapid succession of iterations from various research groups.

In 2023 and 2024, the Inria SODA team introduced TabICL and its successor, TabICLv2, which addressed scaling issues and improved attention mechanisms. Layer 6 contributed TabDPT, while the landscape shifted again in June 2026 with Google Research’s announcement of TabFM. TabFM currently sits at the top of the TabArena leaderboard, though it remains a subject of scrutiny within the community due to the lack of a published technical paper and its non-commercial licensing.

Tabular LLMs: An Introduction to the Foundation Models That Predict Your Spreadsheet

The rapid pace of these releases has caught many practitioners off guard. As of July 15, 2026, the TabArena leaderboard reflects a complete overhaul of the "best-in-class" rankings. While AutoGluon’s heavy ensemble pipelines (which run for several hours) still hold competitive positions, the single-model frontier is now entirely dominated by foundation models.

Independent Verification and Benchmarking Results

To validate these claims, independent researchers recently re-evaluated the TabArena results using the TabICLv2 model. The audit was conducted on an AWS A10G instance, covering 51 datasets ranging from binary classification to complex regression tasks. The datasets varied in size from roughly 750 rows to 150,000 rows.

The findings were striking. The independent run achieved an Elo rating of 1559, closely matching the official leaderboard’s 1575. For 16 of the 51 datasets, the metric values were identical to four decimal places. The median relative difference across the entire sweep was a mere 0.08%, a margin typically attributed to GPU nondeterminism rather than methodological errors.

The efficiency of the foundation model approach was also highlighted by the cost of the audit. The entire 51-dataset sweep, including environment setup, was completed in 2.1 hours for a total cost of approximately $2. In contrast, traditional gradient-boosted decision tree (GBDT) protocols often require hours of hyperparameter tuning per dataset to reach peak performance. TabICLv2’s median "fit" time—which is essentially just data loading and context storage—was 4 seconds per 1,000 rows, roughly 100 times faster than tuned GBDT protocols.

Tabular LLMs: An Introduction to the Foundation Models That Predict Your Spreadsheet

Comparative Performance: The Elo Standings

The TabArena benchmark uses an Elo rating system to compare models, where a standard Random Forest is anchored at 1000. A 400-point gap indicates a 10:1 win probability in head-to-head comparisons.

As of the mid-2026 snapshot, the standings are as follows:

  • TabFM (Google Research): 1713 Elo
  • AutoGluon (Ensemble): 1615 Elo
  • TabICLv2 (Inria): 1590 Elo
  • TabPFN-2.6: 1582 Elo
  • LightGBM (Tuned & Ensembled): 1432 Elo
  • CatBoost (Tuned): 1417 Elo
  • XGBoost (Tuned): 1405 Elo

The data reveals a significant performance gap. Even after giving the GBDT models a full tuning budget and ensembling their outputs, they remain more than 150 Elo points behind the untuned, zero-shot foundation models. This suggests that the structural priors learned by transformers during pretraining are more effective at capturing complex tabular relationships than the iterative partitioning used by decision trees.

The Regime Split: Where Trees Still Hold the Ground

Despite the dominance of foundation models in aggregate scores, the audit identified specific "regimes" where traditional gradient-boosted trees remain superior. This "regime split" provides a crucial roadmap for engineers deciding which tool to deploy.

Tabular LLMs: An Introduction to the Foundation Models That Predict Your Spreadsheet

The first major factor is dimensionality. In datasets with more than 100 features, the performance of foundation models begins to degrade. For example, on the Bioresponse dataset (1,776 features) and the QSAR-TID-11 dataset (1,024 features), GBDTs consistently outperformed TabICLv2. Below the 100-feature threshold, however, the foundation model won nearly 88% of the matchups.

The second factor is the combination of scale and high-cardinality categorical variables. On the Amazon_employee_access dataset—a classic benchmark characterized by high-cardinality features—the foundation model suffered its largest loss, with a 25% error gap compared to the best tree. Furthermore, while foundation models are highly effective on small-to-medium datasets, their win rate against trees drops from 89% for tables under 3,000 rows to approximately 64% for tables exceeding 20,000 rows.

Data Integrity and the Question of Contamination

A recurring concern in the evaluation of any foundation model is benchmark contamination—the possibility that the model "saw" the test data during its pretraining phase. In the realm of tabular data, this risk is mitigated by the use of synthetic pretraining.

Models like TabICLv2 and the original TabPFN are pretrained exclusively on synthetic data generated from random structural causal models (SCMs). These are essentially mathematically generated "fake" datasets that follow plausible cause-and-effect patterns. Because no real-world data enters the pretraining pipeline, there is no risk of leakage from the TabArena benchmark.

Tabular LLMs: An Introduction to the Foundation Models That Predict Your Spreadsheet

However, the industry is seeing a trend toward "hybrid" pretraining. Newer models like RealTabPFN-2.5 have begun incorporating curated corpuses of real-world datasets from OpenML and Kaggle to boost accuracy. While these researchers employ rigorous deduplication pipelines—checking feature names, row hashes, and metadata—the community remains cautious. The audit notes that models with the cleanest provenance (synthetic-only) are currently being out-scored by those using real-world data, creating an "incentive gradient" that may complicate future objective benchmarking.

Industry Implications and the Hybrid Future

The rise of tabular foundation models suggests a looming shift in how enterprise machine learning pipelines are constructed. For many organizations, the ability to get state-of-the-art predictions in seconds without a hyperparameter search is a compelling value proposition, particularly for "cold-start" problems where data is limited.

Analysis of "router" systems—which attempt to choose the best model for a given dataset automatically—indicates that the future may lie in hybrid ensembles. While a deployable router picking between two different foundation models can successfully boost Elo scores, routing between a foundation model and a GBDT is currently more difficult. The validation errors of the two model families are often not directly comparable, leading to sub-optimal selections.

For now, the recommendation for practitioners is clear: for tables with fewer than 100 features and modest row counts, models like TabICLv2 offer a new "gold standard" for open-source performance. For high-dimensional, complex categorical data, the tuned gradient-boosted tree remains an essential tool. As Google’s TabFM and other proprietary models continue to push the ceiling of what is possible, the data science community is entering an era where the transformer may finally do for the spreadsheet what it has already done for text and image.

July 24, 2026 0 comment
0 FacebookTwitterPinterestEmail
Artificial Intelligence & Tech

5 ways Google Search can level up your thrift and vintage shopping

by admin July 24, 2026
written by admin

The global resale market has entered a transformative era in 2026, driven by a convergence of environmental consciousness, economic pragmatism, and rapid advancements in generative artificial intelligence. As search interest for terms like "vintage" and "how to thrift" reaches unprecedented peaks, technology is bridging the gap between the chaotic charm of a second-hand bin and the streamlined efficiency of modern e-commerce. Google has positioned itself at the center of this cultural shift, deploying a suite of AI-driven tools designed to simplify the hunt for unique, pre-loved items. From identifying the provenance of a 1990s leather bag to mapping out a full day of "slow fashion" shopping, the integration of AI into the search experience is fundamentally altering the mechanics of the circular economy.

The Rise of the Digital Thrifting Ecosystem

The surge in interest regarding vintage goods is not merely a fleeting trend but a significant shift in consumer behavior. According to recent search data, interest in "vintage desks" has spiked by 190% over the past year, while "vintage jerseys" and "thrifted heels" have reached all-time highs. This momentum is fueled largely by younger demographics—specifically Gen Z and Millennials—who prioritize individuality and sustainability over the standardized offerings of fast fashion.

5 ways Google Search can level up your thrift and vintage shopping

In response to this demand, Google has refined its Search and Lens capabilities to cater to the "treasure hunter" mindset. The primary challenge of thrifting has historically been the lack of inventory data; unlike big-box retailers, thrift stores rarely have digitized catalogs. To solve this, Google’s AI tools now rely on visual recognition and contextual understanding to help users navigate the opaque world of second-hand retail.

1. Curated Itineraries via AI Mode in Search

One of the most significant hurdles for vintage enthusiasts is the logistical planning required for a successful outing. Unlike a trip to a shopping mall, thrifting often involves visiting multiple disparate locations, ranging from curated boutiques to massive warehouse-style outlets. Google’s "AI Mode in Search" addresses this by allowing for highly specific, multi-layered queries.

By leveraging large language models (LLMs), Search can now process nuanced requests such as, "Where can I find vintage jerseys in San Francisco? Bonus points if there’s a spot I can find a gluten-free brunch after within walking distance." The AI does not merely provide a list of links; it synthesizes data from Google Maps, business reviews, and local directories to present a cohesive plan. This tool effectively acts as a digital concierge, identifying stores that match a specific aesthetic while simultaneously accounting for the user’s dietary preferences and geographic constraints.

5 ways Google Search can level up your thrift and vintage shopping

2. Deep Object Analysis with Google Lens

Google Lens has evolved from a simple image recognition tool into a sophisticated research assistant. For a shopper standing in a crowded flea market, Lens provides immediate clarity on an item’s history and value. By snapping a photo of a garment or piece of furniture, users can access "visual matches" that reveal the original designer, the likely era of production, and the materials used.

This feature is particularly valuable for identifying "hidden gems"—high-value items that may have been mispriced by a vendor. For example, a user might find a crocodile-embossed handbag and use Lens to determine if it is a genuine 1980s designer piece or a modern reproduction. Furthermore, Lens provides an "Estimated Resale Value" by aggregating data from various online marketplaces, allowing the shopper to make an informed decision on whether the asking price represents a fair deal.

3. Seamless Integration with Circle to Search

As social media continues to be a primary source of fashion inspiration, the friction between seeing an item on a screen and finding a vintage equivalent has been a persistent pain point. The "Circle to Search" feature, now a staple on the Android ecosystem, allows users to identify items without leaving their current app. By holding down the home button and circling an image—such as a vintage jersey worn by an influencer—users can instantly trigger a search for similar items across the web.

5 ways Google Search can level up your thrift and vintage shopping

This tool is particularly effective for the "vibe-based" search. Once an item is circled, users can refine the results with follow-up questions like, "What are similar styles with a ’90s vibe?" This iterative search process allows consumers to explore the aesthetic nuances of different decades, helping them find pieces that fit a specific historical look without needing to know the exact technical terminology of the garment.

4. The Digital Dressing Room: Virtual Try-On

One of the greatest deterrents to buying vintage online is the uncertainty of fit and style. Vintage sizing is notoriously inconsistent, and the unique silhouettes of past decades do not always translate well to modern bodies. To mitigate this, Google has introduced "Virtual Try-On" (VTO) capabilities.

The process begins with Lens identifying a similar item to a vintage piece found in a store or online. If a "try it on" option is available, the user can upload a full-body photo of themselves. The AI then overlays the garment onto the user’s image, adjusting for drape, shadows, and body proportions. This digital dressing room experience provides a visual confirmation of whether a "funky vintage jacket" complements the user’s frame, reducing the likelihood of "buyer’s remorse" and the subsequent environmental cost of returns.

5 ways Google Search can level up your thrift and vintage shopping

5. Empowering the Circular Economy through Resale

Thrifting is a two-way street, and Google’s tools are increasingly being used to facilitate the "selling" side of the equation. As closets become cluttered, Lens assists users in decluttering by evaluating the resale potential of their own possessions. By photographing an old item, a user can ask, "Could I resell this?" or "What kind of stores buy items like this?"

The AI analyzes the item’s condition and current market demand to suggest the best platforms for sale—whether it be a local consignment shop, a specialized vintage boutique, or a global peer-to-peer marketplace like Depop or Poshmark. This functionality encourages a "one-in, one-out" philosophy, ensuring that pre-loved goods continue to circulate rather than ending up in landfills.

A Chronology of Innovation: From Text to Vision

The current state of AI-assisted thrifting is the result of a decade-long evolution in search technology.

5 ways Google Search can level up your thrift and vintage shopping
  • 2017: Google Lens is launched, introducing the concept of "searching what you see."
  • 2021: Multitask Unified Model (MUM) technology is integrated, allowing Search to understand information across text and images simultaneously.
  • 2024: The introduction of "Circle to Search" removes the need to switch apps, streamlining the path from inspiration to purchase.
  • 2025-2026: Generative AI becomes the default interface, shifting Search from a directory of websites to a proactive problem-solving engine.

This timeline illustrates Google’s shift toward "multimodal" search, where the input can be a photo, a gesture, or a complex spoken sentence, and the output is a personalized, actionable insight.

Economic and Environmental Implications

The implications of these tools extend far beyond individual convenience. From a macro-economic perspective, the democratization of vintage "expertise" via AI is professionalizing the amateur reseller market. When every shopper has the power to identify a rare label or estimate a fair market price, the efficiency of the secondary market increases.

Environmentally, the impact is even more profound. The fashion industry is responsible for approximately 10% of global carbon emissions. By making second-hand shopping as easy and reliable as buying new, Google is helping to normalize "circularity." When consumers choose a vintage desk over a flat-pack alternative, or a pre-owned jersey over a new one, they are actively reducing the demand for new resource extraction and manufacturing.

5 ways Google Search can level up your thrift and vintage shopping

The Future of AI in Retail

As we look toward the remainder of 2026 and beyond, the role of AI in the thrift and vintage market is expected to deepen. We are likely to see the emergence of "proactive thrifting," where AI agents monitor local estate sales and online listings on behalf of the user, alerting them the moment a "grail" item—a highly sought-after collectible—becomes available.

Furthermore, as augmented reality (AR) hardware becomes more prevalent, the "Virtual Try-On" and Lens features may move from the phone screen to wearable glasses, allowing for a "heads-up" thrifting experience where prices and eras are overlaid directly onto items as a shopper browses a physical store.

In conclusion, the marriage of Google’s AI tools with the vintage movement represents a rare instance where high-tech innovation supports "low-tech" sustainability. By removing the barriers of uncertainty and logistical complexity, Google is not just helping people find old clothes; it is fostering a more intentional, informed, and environmentally responsible way of consuming. In 2026, the best way to move forward in fashion and home decor is, quite literally, to look back—with the help of a powerful AI lens.

July 24, 2026 0 comment
0 FacebookTwitterPinterestEmail
Newer Posts
Older Posts

Recent Posts

  • EF Protocol Cluster Releases Unified Tier List for Hegotäel Upgrade
  • Kraken Expands Its Digital Asset Offerings With the Official Launch of KOR Protocol Token Trading
  • Zcash Ecosystem Faces Pivotal Week with Network Upgrade 7 and Landmark Governance Restructuring
  • Navigating the Digital Identity Crisis: An Illustrated Primer on Anonymous Authentication in the Age of AI and Age-Verification Laws
  • Verifone Integrates Visa Featurespace Adaptive AI to Revolutionize Global Fraud Detection and Payment Security

Recent Comments

No comments to show.
  • Facebook
  • Twitter

@2021 - All Right Reserved. Designed and Developed by PenciDesign


Back To Top
Dr Crypton
  • Home
  • About Us
  • Contact Us
  • Cookies Policy
  • Disclaimer
  • DMCA
  • Privacy Policy
  • Terms and Conditions

We are using cookies to give you the best experience on our website.

You can find out more about which cookies we are using or switch them off in .

Dr Crypton
Powered by  GDPR Cookie Compliance
Privacy Overview

This website uses cookies so that we can provide you with the best user experience possible. Cookie information is stored in your browser and performs functions such as recognising you when you return to our website and helping our team to understand which sections of the website you find most interesting and useful.

Strictly Necessary Cookies

Strictly Necessary Cookie should be enabled at all times so that we can save your preferences for cookie settings.